Friday, March 20, 2020

Python: implementing Strategy design pattern without class hierarchy

The essence of Strategy design pattern is to enable algorithm selection to happen at run-time. Assume we would have the following two simple functions in a source file. Note, that the content of these functions is only a side-show. The main point of interest here is, how do we call these functions from somewhere else.

# functions.py
import numpy as np

def calculate_average(arr):
    return np.mean(arr)

def calculate_standard_deviation(arr):
    return np.std(arr)

In the main program, we need to select desired algorithm to process calculation for array input.

Hard-coded implementation


Below is kind of 'level-one' implementation for the main program. Needless to say, we are forced to modify the program as soon as any new function will be implemented in functions module and we would like to use that new function in the main program.

import functions

try:
    arr = [1, 2, 3, 4, 5]
    selection = 1

    if(selection == 1):
        result = functions.calculate_average(arr)
    elif(selection == 2):
        result = functions.calculate_standard_deviation(arr)
    else:
        raise Exception('Selected function is not implemented.')

    print(result)

except Exception as e:
    print(e)

Flexible implementation


Fortunately, there are ways to get out of such hard-coded scheme for selecting algorithm and this post is only presenting one such possibility. First, let us implement the following json configuration file. In this file, we are configuring the name of the function what we would like to use in our main program.

{
  "function_name": "calculate_standard_deviation"
}

In our new main program, we create configurations from the previous file and read function name from it. Then, by using hasattr function we check, if functions module is containing configured function. After this, we use getattr function to get reference to configured function. Finally, we will use the function and print calculation result.

import json
import functions

try:
    arr = [1, 2, 3, 4, 5]

    # create configurations
    path = '//temp/configurations.json'
    configurations = json.load(open(path, 'r'))
    function_name = configurations['function_name']

    if(hasattr(functions, function_name)):
        function = getattr(functions, function_name)
        result = function(arr)
    else:
        raise Exception('Calculation cannot be processed due to incorrect function configuration.')

    print(result)

except Exception as e:
    print(e)

Assume there would be a new function implementation in functions module and we would like to use that new function in our main program. In this flexible implementation, there would be no need to touch the main program here. Required change (run-time information of what function will be used) has now been isolated to configurations file.

From purely technical point of view, presented scheme is far from being 'traditional' Strategy pattern implementation starting from the fact, that there is no class hierarchy. However, code is receiving run-time instructions (from configurations file) for selecting a specific algorithm (from all functions available). At least for me, this is the essence of Strategy design pattern.

Finally, thanks for reading this blog.
-Mike

Saturday, March 14, 2020

Python: Implementing Flexible Logging Mechanism

This post is presenting a way to implement flexible logging mechanism for Python program. However, just for the sake of being curious, I have also implemented another logging mechanism by using Observer Design Pattern. The both programs can be downloaded from my github page.

For flexible logging, I have the following two criteria:
  1. Number of loggers (medium into which log feed will be written) can be chosen.
  2. Log feed (which will be written into chosen medium) can be chosen, based on log levels.

Using Observer Pattern


import datetime as dt   
import enum

class LogLevel(enum.Enum):
    debug = 1
    info = 2
    warning = 3
    error = 4
    critical = 5
    
# subscriber in observer pattern, receives updates from publisher.
class LogHandler:
    def __init__(self, logging_function, log_level):
        self.logging_function = logging_function
        self.log_level = log_level
    
    # receive update from publisher
    def update_log(self, message, log_level):
        # log levels: debug=1, info=2, warning=3, error=4, critical=5
        # ex. class log level 1 will send log updates for all incoming messages
        if(self.log_level.value <= log_level.value):
            date_time_string = str(dt.datetime.now().strftime("%Y-%m-%d %H:%M:%S"))
            self.logging_function('{} {} {}'.format(date_time_string, log_level.name, message))
        
# publisher in observer pattern, send updates for subscribers.
class Logger:
    def __init__(self):
        self.log_handlers = set()
        
    def register_log_handler(self, log_handler):
        self.log_handlers.add(log_handler)
        
    def unregister_log_handler(self, log_handler):
        self.log_handlers.discard(log_handler)
    
    # send update for all registered subscribers
    def send_log_update(self, message, log_level):
        for log_handler in self.log_handlers:
            log_handler.update_log(message, log_level)  

# create publisher
logger = Logger()

# create console log handler (subscriber), receiving updates only when update message log level is greater than/equal to warning
console_log_handler = LogHandler(lambda message: print(message), LogLevel.warning)
logger.register_log_handler(console_log_handler)

# create file log handler (subscriber), receiving all possible updates
log_file = open('/home/mikejuniperhill/log.txt', 'w')
file_log_handler = LogHandler(lambda message: print(message, file=log_file), LogLevel.debug)
logger.register_log_handler(file_log_handler)

# process log updates
logger.send_log_update('sending calculation task to engine', LogLevel.debug)
logger.send_log_update('engine is processing calculation task', LogLevel.info)
logger.send_log_update('incorrect grid configurations, using backup grid settings', LogLevel.warning)
logger.send_log_update('analytical error retrieved for this calculation task', LogLevel.error)
logger.send_log_update('unable to process calculations task due to incorrect market data', LogLevel.critical)

log_file.close()

Log from processing feed is being printed to console and file, according to the chosen log levels.


Using Python Logging


Python is full of positive surprises and as one might expect, logging issues have already been thoroughly chewed by Python community. More information on in-built logging tools can be read from here. In the program, we create loggers and handlers (for console and file) by using method Initialize_logHandlers. This method uses Configurations object, which will be constructed from a given json file. The content of json configuration file is as follows.

{
  "LOGFORMATSTRING": "%(asctime)s %(levelname)-1s %(filename)-1s %(funcName)-1s %(message)s", 
  "CLEANLOGFILEBEFOREWRITE": 1, 
  "LOGFILEPATH": "/home/mikejuniperhill/log.txt",
  "CONSOLELOGLEVEL": 30,
  "FILELOGLEVEL": 10, 
  "LOGDATEFORMAT": "%d.%m.%Y %H:%M:%S",
  "LOGFILEMODE": "w"
}

The program below will create configurations object from json file, initializes logging handlers (console and file) and process small feed for logger.

import os, logging, json

class Configurations:
    inner = {}
    # read JSON configuration file to dictionary
    def __init__(self, filePathName):
        self.inner = json.load(open(filePathName))
    # return value for a given configuration key
    # 'overload' indexing operator
    def __getitem__(self, key):
        return self.inner[key.upper()]

def Initialize_logHandlers(configurations):
    # conditionally, delete the existing log file before starting to write log for this session
    if(bool(int(configurations['CleanLogFileBeforeWrite'])) == True):
        path = configurations['LogFilePath']
        if(os.path.exists(path) == True): os.remove(path)
 
    # create logger
    logger = logging.getLogger()
    logger.setLevel(logging.NOTSET)
 
    # console log handler
    c_handler = logging.StreamHandler()
    c_handler.setLevel(int(configurations['ConsoleLogLevel']))
    c_formatter = logging.Formatter(configurations['LogFormatString'], datefmt=configurations['LogDateFormat'])
    c_handler.setFormatter(c_formatter)
    logger.addHandler(c_handler)
 
    # file log handler
    f_handler = logging.FileHandler(configurations['LogFilePath'], mode=configurations['LogFileMode'], encoding=None, delay=True)
    f_handler.setLevel(int(configurations['FileLogLevel']))
    f_formatter = logging.Formatter(configurations['LogFormatString'], datefmt=configurations['LogDateFormat'])
    f_handler.setFormatter(f_formatter)
    logger.addHandler(f_handler)

# read configurations for this program
path = '/home/mikejuniperhill/configurations.json'
# create configurations object
configurations = Configurations(path)

# initialize log handlers
Initialize_logHandlers(configurations)
 
# process log updates
logging.debug('sending calculation task to engine')
logging.info('engine is processing calculation task')
logging.warning('incorrect grid configurations, using backup grid settings')
logging.error('analytical error retrieved for this calculation task')
logging.critical('unable to process calculations task due to incorrect market data')

Log from processing feed is being printed to console and file, according to the chosen log levels.


Finally, thanks for reading this blog.
-Mike

Saturday, March 7, 2020

Python: Implementing Factory Method Design Pattern

Ideally, program should be closed for modifications, but open for extensions and hard-coded stuff should be avoided like plague. This is the point, where Design Patterns are usually stepping into picture. When the code base will grow enough in size and we are in charge of production-level programs, it is relatively easy to justify the usage of patterns. In this post, Python mutation of Factory Method Pattern is introduced for creating Task class objects, based on argument feed received from different types of sources. Complete program can be downloaded from my github page.

Imaginary scheme


Third-party analytical software is used for processing different types of complex calculations. One calculation request requires a set of specific arguments from the client program. Moreover, different types of requests will require different set of arguments (number of arguments, types of arguments). Before sending calculation request for analytical software, client program must collect arguments for all tasks to be processed from somewhere and we would like to leave the source for such task arguments open (json, text, console, xml, etc.).

Json source file


{
  "taskName": "ANZ.XVA",
  "taskType": "XVA",
  "paths": 1000,
  "storeExposures": "True" 
}

Text source file


taskName,RBC.PV
taskType,PV

Program


import sys, json, csv

# class for hosting calculation task-related information
# NOTE: the actual method for creating 'calculation request' is currently not implemented
class Task(object):
    def __init__(self, arguments):
        self.arguments = arguments
        
    # non-relevant dummy method, which just writes out given arguments
    def print(self):
        for k, v in self.arguments.items():
            print(k, 'is', v)
        
    @classmethod
    # factory: create task object from json file
    def from_json(cls, path)->'Task':
        arguments = json.load(open(path, 'r'))
        return cls(arguments)
    
    @classmethod
    # factory: create task object from text file
    def from_text(cls, path)->'Task':
        arguments = dict((k, v) for k, v in csv.reader(open(path, 'r')))
        return cls(arguments)
    
    @classmethod
    # factory: create task object from console input
    def from_console(cls)->'Task':
        arguments = json.loads(input())
        return cls(arguments)        

path = '/home/mikejuniperhill/json.feed/task.json'
task = Task.from_json(path)
task.print()

path = '/home/mikejuniperhill/json.feed/task.txt'
task = Task.from_text(path)
task.print()

task = Task.from_console()
# console feed string: {"taskName":"ANZ.WHATIF.XVA","taskType":"WHATIF","referenceTask":"ANZ.XVA"}
task.print()

Program output


Thanks for reading this blog.
-Mike


Monday, March 2, 2020

Python: Simulating Exposures Using Multiprocessing Pool

This post is presenting a scheme for simulating exposures for European call option on a non-dividend-paying stock by using Multiprocessing.Pool class (note: in Linux). There are several different options available when stepping into multiprocessing world, but for this specific purpose, Multiprocessing.Pool is robust enough. In a nutshell, we need to simulate a path for the underlying equity price and then calculate call option present value for each point in time. Complete program can be downloaded from my github.

Library imports


import multiprocessing as mp
import numpy as np
import scipy.stats as sc
import matplotlib.pyplot as pl
import time, math

Methods


# black scholes valuation of call option on non-dividend-paying equity
def VanillaCall(s, x, t, r, v):
    pv = 0.0
    # option value at maturity
    if((t - 0.0) < (1 / 365)):
        pv = max(s - x, 0.0)
    # option value before its maturity
    else:
        d1 = (math.log(s / x) + (r + 0.5 * v ** 2) * t) / (v * math.sqrt(t))
        d2 = (math.log(s / x) + (r - 0.5 * v ** 2) * t) / (v * math.sqrt(t))
        pv = (s * sc.norm.cdf(d1, 0.0, 1.0) - x * math.exp(-r * t) * sc.norm.cdf(d2, 0.0, 1.0))
    return pv

# globalize local parameters
def Globalizer(local_parameters):
    global global_parameters
    global_parameters = local_parameters

# simulate exposures by using
# - a given one-factor process (func_process)
# - a given pricing function (func_pricing)
def SimulateExposures(arg):
    # seed random number generator
    np.random.seed(arg)
    # unzip globalized tuple
    n_paths_per_process, n_steps, t, s_0, r, vol, func_pricing, func_process = global_parameters
    s = 0.0
    pv = 0.0
    dt = (t / n_steps)
    # create container for results
    paths = np.zeros(shape=(n_paths_per_process, n_steps + 1), dtype=float)
    for i in range(n_paths_per_process):
        s = s_0
        t_expiry = t
        # value product at path inception
        paths[i, 0] = func_pricing(s, t_expiry)
        # create array of normal random variates
        e = np.random.standard_normal(n_steps)
        for j in range(n_steps):
            s = func_process(s, e[j])
            t_expiry = (t - dt * (j + 1))
            # value product at after inception
            paths[i, j + 1] = func_pricing(s, t_expiry)
    return paths

Main program


The main program will create a pool containing two processes, which will use SimulateExposures method for calculating exposures for a call option. Method takes only random seed as its direct input argument. All the other required arguments (product- or process-related parameters) will be packed into tuple data structure, which will be globalized for each process separately in initializer method. After processing, the both worker methods will return an array of simulated exposures, which then will be aggregated into array (exposures).

t_0 = time.time()

# monte carlo parameters
n_paths = 10000
n_steps = 250
n_processes = 2
n_paths_per_process = int(n_paths / n_processes)
seeds = np.random.randint(low=1, high=999999, size=n_processes)

# product- and process-related parameters
t = 1.0
s_0 = 100.0
r = 0.05
vol = 0.15
x = 100.0
drift = ((r - 0.5 * vol * vol) * (t / n_steps))
diffusion = (vol * math.sqrt(t / n_steps))

# method for calculating pv as a function of spot and time to maturity
func_pricing = lambda s_, t_: VanillaCall(s_, x, t_, r, vol)
# method for simulating stochastic process
func_process = lambda s_, e_: s_ * math.exp(drift + diffusion * e_)

# container for storing results from worker methods
results = []

# local parameters, which will be globalized for pool workers
simulation_parameters = (n_paths_per_process, n_steps, t, s_0, r, vol, func_pricing, func_process)
pool = mp.Pool(processes=n_processes, initializer=Globalizer, initargs=(simulation_parameters,))
for r in pool.imap_unordered(SimulateExposures, seeds): results.append(r)

t_1 = time.time()
print('processing time', t_1 - t_0)

# stack results from workers into one array
exposures = np.empty(shape = (0, results[0].shape[1]))
for i in range(n_processes):
    exposures = np.vstack([exposures, results[i]])

# average of all exposures
expected_exposure = np.mean(exposures, axis=0)
pl.plot(expected_exposure)
pl.show()

Thanks for reading this blog.
-Mike

Thursday, November 28, 2019

QuantLib-Python: Heston Monte Carlo Valuation for Autocallable Memory Coupon Note

In the spirit of the previous post, I was woodshedding an implementation for valuing Autocallable Memory Coupon note by using libraries available in QuantLib-Python. These products are embedding a series of out-of-the-money barrier options and for this specific reason, it is important to capture implied volatility smile by using appropriate model. For this implementation example, Heston stochastic volatility model has been used. In addition to the actual Monte Carlo algorithm and path generator, I also implemented a simple method for calibrating Heston model to volatility surface by using SciPy optimization package. The complete program can be downloaded from my GitHub page.

Autocallable Notes


Autocallable notes are path-dependent structured products, which may be linked to any index. However, this product is usually linked to equity index or equity basket. If condition called autocall barrier will be reached on any coupon date, the product will be terminated immediately, after paying back coupon (usually fixed) and notional amount. However, if the underlying index will not reach autocall barrier on a coupon date, but reaches condition called coupon barrier, only fixed coupon will be paid on notional and the product will be kept alive until maturity (or until the next autocall event). Autocallables may also have a memory, which means that if the underlying index was below coupon barrier in the previous coupon date (and there was no coupon payment), but will be above coupon barrier in the next coupon date, the product will pay all cumulated (and unpaid) coupons on notional in the next coupon date. Autocallable products are (usually) not capital protected, which means that the investor is not guaranteed to receive the initial investment. If the index fixing on a final coupon date will be below condition called protection barrier, the final redemption amount will be calculated according to specific formula and investor will lose some of the invested capital. There is an example brochure and term sheet available for this product in my GitHub page.

Library Imports


import QuantLib as ql
import numpy as np
import scipy.optimize as opt

Heston Path Generator


Below is a simple (hard-coded) method for generating paths by using Heston process for a given set of QuantLib dates, which can be unevenly distributed. A couple of notes about Heston path generation process in general. QuantLib MultiPathGenerator has to be used for simulating paths for this specific process, because "under the hood", QuantLib simulates two correlated random variates: one for the asset and another for the volatility. As a result for "one simulation round", MultiPath object will be received from generator. This MultiPath object contains generated paths for the both asset and volatility (multiPath[0] = asset path, multiPath[1] = volatility path). So, for any further purposes (say, to use simulated asset path for something), one can just use generated asset path and ignore volatility path. However, volatility path is available, if there will be some specific purpose for obtaining the information on how volatility has been evolving over time.

# hard-coded generator for Heston process
def HestonPathGenerator(dates, dayCounter, process, nPaths):
    t = np.array([dayCounter.yearFraction(dates[0], d) for d in dates])
    nGridSteps = (t.shape[0] - 1) * 2
    sequenceGenerator = ql.UniformRandomSequenceGenerator(nGridSteps, ql.UniformRandomGenerator())
    gaussianSequenceGenerator = ql.GaussianRandomSequenceGenerator(sequenceGenerator)
    pathGenerator = ql.GaussianMultiPathGenerator(process, t, gaussianSequenceGenerator, False)
    paths = np.zeros(shape = (nPaths, t.shape[0]))
    
    for i in range(nPaths):
        multiPath = pathGenerator.next().value()
        paths[i,:] = np.array(list(multiPath[0]))
        
    # return array dimensions: [number of paths, number of items in t array]
    return paths

Heston Model Calibration


Below is a simple (hard-coded) method for calibrating Heston model into a given volatility surface. Inside this method, process, model and engine are being created. After this, calibration helpers for Heston model are being created by using given volatility surface data. Finally, calibrated model and process are being returned for any further use. The actual optimization workhorse will be given outside of this method. For this specific example program, SciPy's Differential Evolution solver is being used, in order to guarantee global minimization result.

# hard-coded calibrator for Heston model
def HestonModelCalibrator(valuationDate, calendar, spot, curveHandle, dividendHandle, 
    v0, kappa, theta, sigma, rho, expiration_dates, strikes, data, optimizer, bounds):
    
    # container for heston calibration helpers
    helpers = []
    
    # create Heston process, model and pricing engine
    # use given initial parameters for model
    process = ql.HestonProcess(curveHandle, dividendHandle, 
        ql.QuoteHandle(ql.SimpleQuote(spot)), v0, kappa, theta, sigma, rho)
    model = ql.HestonModel(process)
    engine = ql.AnalyticHestonEngine(model)
    
    # nested cost function for model optimization
    def CostFunction(x):
        parameters = ql.Array(list(x))        
        model.setParams(parameters)
        error = [helper.calibrationError() for helper in helpers]
        return np.sqrt(np.sum(np.abs(error)))

    # create Heston calibration helpers, set pricing engines
    for i in range(len(expiration_dates)):
        for j in range(len(strikes)):
            expiration = expiration_dates[i]
            days = expiration - valuationDate
            period = ql.Period(days, ql.Days)
            vol = data[i][j]
            strike = strikes[j]
            helper = ql.HestonModelHelper(period, calendar, spot, strike,
                ql.QuoteHandle(ql.SimpleQuote(vol)), curveHandle, dividendHandle)
            helper.setPricingEngine(engine)
            helpers.append(helper)
    
    # run optimization, return calibrated model and process
    optimizer(CostFunction, bounds)
    return process, model

Monte Carlo Valuation


The actual Autocallable valuation algorithm has been implemented in this part of the code. For the sake of being able to value this product also after its inception, valuation method takes past fixings as Python dictionary (key: date, value: fixing). Now, if one changes valuation date to any possible date after inception and before transaction maturity, the product will also be valued accordingly. It should be noted, that in such scheme it is crucial to provide all possible past fixings. Failure to do this, will lead to an exception. Algorithm implementation is a bit long and might look scary, but it is actually really straightforward if one is familiar enough with this specific product.

def AutoCallableNote(valuationDate, couponDates, strike, pastFixings, 
    autoCallBarrier, couponBarrier, protectionBarrier, hasMemory, finalRedemptionFormula, 
    coupon, notional, dayCounter, process, generator, nPaths, curve):    
    
    # immediate exit trigger for matured transaction
    if(valuationDate >= couponDates[-1]): return 0.0
    
    # immediate exit trigger for any past autocall event
    if(valuationDate >= couponDates[0]):
        if(max(pastFixings.values()) >= (autoCallBarrier * strike)): return 0.0

    # create date array for path generator
    # combine valuation date and all the remaining coupon dates
    dates = np.hstack((np.array([valuationDate]), couponDates[couponDates > valuationDate]))
    
    # generate paths for a given set of dates, exclude the current spot rate
    paths = generator(dates, dayCounter, process, nPaths)[:,1:]
    
    # identify the past coupon dates
    pastDates = couponDates[couponDates <= valuationDate]

    # conditionally, merge given past fixings from a given dictionary and generated paths
    if(pastDates.shape[0] > 0):
        pastFixingsArray = np.array([pastFixings[pastDate] for pastDate in pastDates])        
        pastFixingsArray = np.tile(pastFixingsArray, (paths.shape[0], 1))
        paths = np.hstack((pastFixingsArray, paths))
    
    # result accumulator
    global_pv = []
    expirationDate = couponDates[-1]
    hasMemory = int(hasMemory)
    
    # loop through all simulated paths
    for path in paths:
        payoffPV = 0.0
        unpaidCoupons = 0
        hasAutoCalled = False
        
        # loop through set of coupon dates and index ratios
        for date, index in zip(couponDates, (path / strike)):
            # if autocall event has been triggered, immediate exit from this path
            if(hasAutoCalled): break
            payoff = 0.0
                
            # payoff calculation at expiration
            if(date == expirationDate):
                # index is greater or equal to coupon barrier
                # pay 100% redemption, plus coupon, plus conditionally all unpaid coupons
                if(index >= couponBarrier):
                    payoff = notional * (1 + (coupon * (1 + unpaidCoupons * hasMemory)))
                # index is greater or equal to protection barrier and less than coupon barrier
                # pay 100% redemption, no coupon
                if((index >= protectionBarrier) & (index < couponBarrier)):
                    payoff = notional
                # index is less than protection barrier
                # pay redemption according to formula, no coupon
                if(index < protectionBarrier):
                    # note: calculate index value from index ratio
                    index = index * strike
                    payoff = notional * finalRedemptionFormula(index)
                
            # payoff calculation before expiration
            else:
                # index is greater or equal to autocall barrier
                # autocall will happen before expiration
                # pay 100% redemption, plus coupon, plus conditionally all unpaid coupons
                if(index >= autoCallBarrier):
                    payoff = notional * (1 + (coupon * (1 + unpaidCoupons * hasMemory)))
                    hasAutoCalled = True
                # index is greater or equal to coupon barrier and less than autocall barrier
                # autocall will not happen
                # pay coupon, plus conditionally all unpaid coupons
                if((index >= couponBarrier) & (index < autoCallBarrier)):
                    payoff = notional * (coupon * (1 + unpaidCoupons * hasMemory))
                    unpaidCoupons = 0
                # index is less than coupon barrier
                # autocall will not happen
                # no coupon payment, only accumulate unpaid coupons
                if(index < couponBarrier):
                    payoff = 0.0
                    unpaidCoupons += 1                    

            # conditionally, calculate PV for period payoff, add PV to local accumulator
            if(date > valuationDate):
                df = curveHandle.discount(date)
                payoffPV += payoff * df
            
        # add path PV to global accumulator
        global_pv.append(payoffPV)
        
    # return PV
    return np.mean(np.array(global_pv))

Main Program


Finally, in this part of the program we will actually use the stuff presented above. First, the usual QuantLib-related parameters are being created, as well as parameters for Autocallable product. Note, that since in this example we are valuing this product at inception, there is no need to provide any past fixings for valuation method (however, it is not forbidden either). After this, interest rate curve and dividend curve will be created, as well as volatility surface data for calibration purposes. Next, initial guesses for Heston parameters will be set and the model will then be calibrated by using dedicated method. Finally, calibrated process will be given to the actual valuation method and Monte Carlo valuation will be processed.

# general QuantLib-related parameters
valuationDate = ql.Date(20,11,2019)
ql.Settings.instance().evaluationDate = valuationDate
convention = ql.ModifiedFollowing
dayCounter = ql.Actual360()
calendar = ql.TARGET()

# Autocallable Memory Coupon Note
notional = 1000000.0
spot = 3550.0
strike = 3550.0
autoCallBarrier = 1.0
couponBarrier = 0.8
protectionBarrier = 0.6
finalRedemptionFormula = lambda indexAtMaturity: min(1.0, indexAtMaturity / strike)
coupon = 0.05
hasMemory = True

# coupon schedule for note
startDate = ql.Date(20,11,2019)
firstCouponDate = calendar.advance(startDate, ql.Period(1, ql.Years))
lastCouponDate = calendar.advance(startDate, ql.Period(7, ql.Years))
couponDates = np.array(list(ql.Schedule(firstCouponDate, lastCouponDate, ql.Period(ql.Annual), 
    calendar, ql.ModifiedFollowing, ql.ModifiedFollowing, ql.DateGeneration.Forward, False)))

# create past fixings into dictionary
pastFixings = {}
#pastFixings = { ql.Date(20,11,2020): 99.0, ql.Date(22,11,2021): 99.0 }

# create discounting curve and dividend curve, required for Heston model
curveHandle = ql.YieldTermStructureHandle(ql.FlatForward(valuationDate, 0.01, dayCounter))
dividendHandle = ql.YieldTermStructureHandle(ql.FlatForward(valuationDate, 0.0, dayCounter))

# Eurostoxx 50 volatility surface data
expiration_dates = [ql.Date(19,6,2020), ql.Date(18,12,2020), 
    ql.Date(18,6,2021), ql.Date(17,12,2021), ql.Date(17,6,2022),
    ql.Date(16,12,2022), ql.Date(15,12,2023), ql.Date(20,12,2024), 
    ql.Date(19,12,2025), ql.Date(18,12,2026)]

strikes = [3075, 3200, 3350, 3550, 3775, 3950, 4050]

data = [[0.1753, 0.1631, 0.1493, 0.132 , 0.116 , 0.108 , 0.1052],
       [0.1683, 0.1583, 0.147 , 0.1334, 0.1212, 0.1145, 0.1117],
       [0.1673, 0.1597, 0.1517, 0.1428, 0.1346, 0.129 , 0.1262],
       [0.1659, 0.1601, 0.1541, 0.1474, 0.1417, 0.1381, 0.1363],
       [0.1678, 0.1634, 0.1588, 0.1537, 0.1493, 0.1467, 0.1455],
       [0.1678, 0.1644, 0.1609, 0.1572, 0.1541, 0.1522, 0.1513],
       [0.1694, 0.1666, 0.1638, 0.1608, 0.1584, 0.1569, 0.1562],
       [0.1701, 0.168 , 0.166 , 0.164 , 0.1623, 0.1614, 0.161 ],
       [0.1715, 0.1698, 0.1682, 0.1667, 0.1654, 0.1648, 0.1645],
       [0.1724, 0.171 , 0.1697, 0.1684, 0.1675, 0.1671, 0.1669]]

# initial parameters for Heston model
theta = 0.01
kappa = 0.01
sigma = 0.01
rho = 0.01
v0 = 0.01

# bounds for model parameters (1=theta, 2=kappa, 3=sigma, 4=rho, 5=v0)
bounds = [(0.01, 1.0), (0.01, 10.0), (0.01, 1.0), (-1.0, 1.0), (0.01, 1.0)]

# calibrate Heston model, print calibrated parameters
calibrationResult = HestonModelCalibrator(valuationDate, calendar, spot, curveHandle, dividendHandle, 
        v0, kappa, theta, sigma, rho, expiration_dates, strikes, data, opt.differential_evolution, bounds)
print('calibrated Heston parameters', calibrationResult[1].params())

# monte carlo parameters
nPaths = 10000

# request and print PV
PV = AutoCallableNote(valuationDate, couponDates, strike, pastFixings, 
    autoCallBarrier, couponBarrier, protectionBarrier, hasMemory, finalRedemptionFormula, 
    coupon, notional, dayCounter, calibrationResult[0], HestonPathGenerator, nPaths, curveHandle)

print(PV)

Finally, thanks for reading this blog and have a pleasant wait for the coming Christmas.
-Mike

Sunday, November 17, 2019

QuantLib-Python: Monte Carlo Valuation for Target Accrual Redemption Note

Out of curiosity, I wanted to create an implementation for interest rate Target Accrual Redemption Note (TARN) by using QuantLib-Python library. Now, as one might be aware, the availability of QuantLib Monte Carlo framework for Python is limited (due to templatization of the original C++ classes) to a few existing implementations. This means, that one is not able to re-implement new MC valuation scheme directly by using this specific framework. What to do? There are some workarounds. One may implement such a new scheme by using QuantLib C++ library and then create a wrapper for this library by using SWIG. Some instructions on how to proceed with the SWIG path has also been presented in here. Another way is just to give up the usual QuantLib "Instrument/Engine"-paradigm and just use all the nice pieces available. The complete program can be downloaded from my GitHub page.

TARN


This product is a path-dependent structured note, which terminates when target coupon payment will be reached. When cumulative coupon amount reaches this target amount before maturity, the holder of the note receives final payment and the contract will terminate immediately. TARN coupon payoff is usually structured to be similar to inverse floating rate note. There is (usually) also an attractive teaser coupon attached in the beginning of the structure, combined with the possibility of getting back the par value relatively fast. If the future index will stay low or go even lower, target coupon will be reached early and the investor will enjoy the benefits of high returns for this short-lived investment. However, in the worst case, if the future index path will go sky high, investor will be "bleeding to death" with this long-dated investment yielding inferior returns.

Path Generator


For this specific implementation (for the sake of being as accurate as possible), I gave up using QuantLib Path Generator, because it will create stochastic paths only for even set of points in time. Below is a simple method, which generates paths for a given set of QuantLib dates, which can be unevenly distributed.

# path generator for a given 1d stochastic process and 
# a given set of QuantLib dates, which can be unevenly distributed
# uses process evolve method, which returns asset value after time interval Δt
# returns E(x0,t0,Δt) + S(x0,t0,Δt) ⋅ Δw, where E is expectation and S standard deviation
# input arguments:
#   x0 = asset value at inception
#   dates = array of dates
#   dayCounter = QuantLib day counter
#   process = QuantLib 1D stochastic process implementation
#   nPaths = number of paths to be simulated
def PathGenerator(x0, dates, dayCounter, process, nPaths):
    t = np.array([dayCounter.yearFraction(dates[0], d) for d in dates])    
    urg = ql.UniformRandomGenerator()
    ursg = ql.UniformRandomSequenceGenerator(t.shape[0] - 1, urg)
    grsg = ql.GaussianRandomSequenceGenerator(ursg)    
    paths = np.zeros(shape = (nPaths, t.shape[0]))
    
    for j in range(nPaths):
        dw = np.array(list(grsg.nextSequence().value()))
        x = x0
        path = []

        for i in range(1, t.shape[0]):
            x = process.evolve(t[i-1], x, (t[i] - t[i-1]), dw[i-1])
            path.append(x)
            
        path = np.hstack([np.array([x0]), np.array(path)])
        paths[j,:] = path
        
    # return array dimensions: [number of paths, number of items in t array]
    return paths

Main Program


First, we create the usual set of required QuantLib parameters, such as valuation date. For the sake of being able to value this product also after its inception, valuation method takes QuantLib Index object as one argument. All past fixing dates and rates can be stored into this index. Now, if one changes valuation date (currently 4.3.2018) to any possible date after inception and before transaction maturity, the product will be valued accordingly. It should be noted, that in such scheme it is crucial to provide all possible past fixings. Failure to do this, will lead to an exception.

For creating valuation curve (curveHandle) and short rate process (HW1F), I have decided to take the shortest possible way and just created flat forward curve and assumed constants for short rate process parameters (mean reversion and short rate volatility), instead calibrating this model into the actual market data. For any "real-life" purposes, one may take a look at some possible proper implementations given in here for valuation curve and in here for model calibration.

Next, all transaction parameters are being created one by one. Coupon dates are being created by using QuantLib Schedule object. Finally, PV and the average termination time point is requested from TARN method and printed.

import QuantLib as ql
import numpy as np

# define general QuantLib-related parameters
valuationDate = ql.Date(4,3,2018)
calendar = ql.TARGET()
convention = ql.ModifiedFollowing
dayCounter = ql.Actual360()
ql.Settings.instance().evaluationDate = valuationDate

# set index object and past fixings
pastFixingsDates = np.array([ql.Date(4,3,2019), ql.Date(4,3,2020)])
pastFixingsRates = np.array([0.05, 0.05])
index = ql.USDLibor(ql.Period(12, ql.Months))
index.clearFixings()
index.addFixings(pastFixingsDates, pastFixingsRates)

# create discounting curve and process for short rate
r0 = 0.015
curveHandle = ql.YieldTermStructureHandle(ql.FlatForward(valuationDate, r0, dayCounter))
a = 0.05
vol = 0.009
HW1F = ql.HullWhiteProcess(curveHandle, a, vol)

# define bond-related parameters
startDate = ql.Date(4,3,2018)
firstCouponDate = calendar.advance(startDate, ql.Period(1, ql.Years))
lastCouponDate = calendar.advance(startDate, ql.Period(10, ql.Years))
couponDates = np.array(list(ql.Schedule(firstCouponDate, lastCouponDate, ql.Period(ql.Annual), 
    calendar, ql.ModifiedFollowing, ql.ModifiedFollowing, ql.DateGeneration.Forward, False)))
teaserCoupon = np.array([0.1])
targetCoupon = 0.25
hasToReachTarget = True
cap = 0.15
floor = 0.0
fixedRate = 0.1
factor = 3.0
structuredCouponPayoff = lambda r: max(fixedRate - factor * r, 0.0)
notional = 1000000.0

# define monte carlo-related parameters
nPaths = 10000

# request result (PV and average termination point)
result = TARN(startDate, valuationDate, couponDates, targetCoupon, teaserCoupon,
    cap, floor, hasToReachTarget, structuredCouponPayoff, notional, dayCounter,
    nPaths, HW1F, curveHandle, index)

print('pv', '{0:.0f}'.format(result[0]))
print('termination', '{0:.1f}'.format(result[1]))

Valuation Method


The last piece of code shows the actual pricing method. Paths will be generated for all remaining coupon dates. Past fixing rates will be used for all such coupon dates, which happened in the past.

All simulated paths will then be processed in the loop. Thanks to amazing variety of different types of array operations in Numpy Array library, we can process a path without deploying any typical "inner loop" (for path steps). The loop basically starts with a given set of simulated rates and along the way, transforms this path into an array of cash flow present values. Operations are commented in the code.

def TARN(bondStartDate, valuationDate, couponDates, targetCoupon, teaserCoupon, cap, floor,
    hasToReachTarget, payoff, notional, dayCounter, nPaths, process, curve, index):    
    
    # immediate exit trigger for matured transaction
    if(valuationDate >= couponDates[-1]):
        return (0.0, 0.0)
    
    # create date array for path generator
    # combine valuation date and all remaining coupon dates
    dates = np.hstack((np.array([valuationDate]), couponDates[couponDates > valuationDate]))
    
    # generate paths for a given set of dates, exclude the current spot rate
    paths = PathGenerator(process.x0(), dates, dayCounter, process, nPaths)[:,1:]
    
    # identify past coupon dates
    pastDates = couponDates[couponDates <= valuationDate]
    # conditionally, merge given past fixings and generated paths
    if(pastDates.shape[0] > 0):
        pastFixings = np.array([index.fixing(pastDate) for pastDate in pastDates])    
        pastFixings = np.tile(pastFixings, (paths.shape[0], 1))
        paths = np.hstack((pastFixings, paths))
        
    # define time grid for all coupon dates, calculate day count fractions
    t = np.array([0.0] + [dayCounter.yearFraction(bondStartDate, d) for d in couponDates])
    dcf = np.diff(t)
    
    # result accumulators
    global_pv = []
    termination = []

    # calculate PV for all paths
    for path in paths:
        # transform simulated path into structured rates using payoff function
        path = (np.vectorize(payoff))(path)
        index_1 = np.where(teaserCoupon > 0.0)
        # replace some path rates with teaser coupons (if exists)
        path[index_1] = teaserCoupon
        # calculate capped and floored structured coupon for non-teaser rates
        path = np.concatenate([path[index_1], np.minimum(path[index_1[0].shape[0]:], cap)])
        path = np.concatenate([path[index_1], np.maximum(path[index_1[0].shape[0]:], floor)])
        # multiply rates with day count fractions
        path = np.multiply(path, dcf)
        # take into account only rates, for which cumulative sum is less or equal to target coupon
        index_2 = np.where(np.cumsum(path) <= targetCoupon)
        path = path[index_2]
        dates = couponDates[index_2]
        # path termination time is the date, which reaches target coupon
        termination.append(dayCounter.yearFraction(valuationDate, dates[-1]))
        # if coupon has to reach target coupon, add remaining coupon available into final coupon
        if(hasToReachTarget): path[-1] = targetCoupon - np.sum(path[:-1])
        # multiply coupon rates with notionals, add final redemption
        path *= notional
        path[-1] += notional
        # take into account only coupons, for which coupon dates are in the future
        index_3 = np.where(dates >= valuationDate)
        dates = dates[index_3]
        path = path[index_3]
        # request discount factors for all coupon dates
        df = np.array([curve.discount(d) for d in dates])
        # calculate coupon PV's
        path = np.multiply(path, df)
        # add path PV into result accumulator
        global_pv.append(np.sum(path))

    # return tuple (pv, average termination time)
    return (np.mean(np.array(global_pv)), np.mean(np.array(termination)))

A couple of final notes. The presented example is valuing a product in which the coupon is exposed to interest rates. However, a notable amount of TARN products issued (in the past), have been exposing their coupons to movements in FX rates. Since any one-dimensional process can be used for path generation purposes in the valuation method, there is a possibility to use some of the existing QuantLib processes also for modeling the path of future FX rates. Also, structured coupon payoff can be defined outside the valuation method. Since all types of TARN products are (usually) pretty much sharing the same other properties (ex. path-dependency, teaser rates), the valuation method is relatively "generic" after all.

Thanks for reading this blog.
-Mike

Wednesday, October 30, 2019

QuantLib-Python: Note on ForwardCurve Construction

In this post, we will construct QuantLib ForwardCurve instance and investigate the resulting term structure of discount factors. Python program and Excel can be downloaded from my GitHub page. First, let us assume the following market data containing [A] one cash deposit and three interpolated rates from futures strip.


After completing bootstrapping procedure, we should get [B] simple spot discount factors and [C] simple forward rates. Next, let us implement this scheme in QuantLib. Import QuantLib libraries and create relevant date objects. Then, set forward rates (from [C]), dates and create QuantLib forward curve instance.

import QuantLib as ql
today = ql.Date(30, 10, 2019)
ql.Settings.instance().evaluationDate = today  
settlementDate = ql.TARGET().advance(today, ql.Period(2, ql.Days))

rts = [0.03145, 0.03145, 0.0278373626373627, 0.0253076923076923, 0.0249373626373629]
dts = [settlementDate, ql.Date(1,2,2020), ql.Date(1,5,2020), ql.Date(1,8,2020), ql.Date(1,11,2020)]
c = ql.ForwardCurve(dts, rts, ql.Actual360(), ql.NullCalendar(), ql.BackwardFlat())
df = [c.discount(d) for d in dts]
print(df)

We get the following set of spot discount factors from the curve instance.
[1.0, 0.9919949898918935, 0.9851153255552918, 0.9787646299045335, 0.9725469122728971]
Note, that these are not what we expected to see. "The correct ones" are calculated in the column [B] in the example above. The issue here is, that when constructing ForwardCurve object, the given forward rates inputs are implicitly defined as continuously compounded rates. Assuming we would like to get the same discount factor term structure as in our example above in [B], we need to convert our forward rate inputs from simple to continuously compounded rates. Let us implement this in QuantLib. Convert simple rates to continuous rates. Then, reset forward rates and re-create QuantLib forward curve instance.

for i in range(len(rts) - 1):
    r_simple = ql.InterestRate(rts[i + 1], ql.Actual360(), ql.Simple, ql.Once)
    t = ql.Actual360().yearFraction(dts[i], dts[i + 1])
    r_continuous = r_simple.equivalentRate(ql.Continuous, ql.NoFrequency, t)
    rts[i + 1] = r_continuous.rate()
    
# set rate for the first node
rts[0] = rts[1]
c = ql.ForwardCurve(dts, rts, ql.Actual360(), ql.NullCalendar(), ql.BackwardFlat())
df = [c.discount(d) for d in dts]
print(df)

We get the following "correct" set of spot discount factors from the curve instance.
[1.0, 0.9920268596783518, 0.9851707210231435, 0.9788400520709886, 0.9726415228427708]
Inputs (dates and forward rates) for ForwardCurve object are defined in yellow box in column [E] below.


ForwardCurve object interpolation scheme is backward flat. This means, that for the final period (from 1-Aug-20 to 1-Nov-20), forward rate of 2.48582% will be applied. Implicitly this means, that there is no practical use for the first given forward rate (at the node, where the date is 1-Nov-19). However, this rate has to be defined anyway.

Note, that QuantLib logic of constructing ForwardCurve object is completely correct. One should just be aware of the fact, that input forward rates given are handled implicitly as continuously compounded rates.

Finally, there are some other types of issues concerning forward rate interpolation, which might be worth of knowing when working with ForwardCurve object. These issues are fully explained in this video given by QuantLib lead developer Luigi Ballabio.

As always, thanks for reading this blog.
-Mike

Sunday, October 20, 2019

Python-QuantLib-SciPy: Optimizing Smooth Libor Forward Curve Revisited

One reader was making a remark, that my implementation for curve calibration scheme as presented in here, was not implemented by using QuantLib. As I was re-thinking my implementation, I suddenly remembered that in QuantLib, there are actually several ways to create yield term structures. One such approach is to create yield term structure from a set of given dates and forward rates. Also, VanillaSwap class gives us a direct mechanism for valuing swap transaction by using constructed curve. Bingo. So, this post is re-visiting curve calibration scheme, but this time implemented by using relevant QuantLib-Python library tools.

A few words about utility classes. Convert class will be used for transforming specific in-built data types into specific QuantLib types (Date, Calendar, DayCounter, etc). VanillaSwap class is just a wrapper for corresponding QuantLib.VanillaSwap class. It should be noted, that there is conventional NPV method for requesting swap PV by giving two specific arguments (yield term structure and floating leg index). There is also another method NPV_calibration, which is used for calculating swap PV during calibration process. For this method, input arguments are list of forward rates, list of forward dates and list of initial market rates. From this information, specific yield term structure implementation (QuantLib.ForwardCurve) will be created and used for valuing swap transaction.

import re
import numpy as np
import scipy.optimize as opt
import matplotlib.pyplot as pl
import QuantLib as ql

# utility class for different QuantLib type conversions 
class Convert():
    
    # convert date string ('yyyy-mm-dd') to QuantLib Date object
    def to_date(s):
        monthDictionary = {
            '01': ql.January, '02': ql.February, '03': ql.March,
            '04': ql.April, '05': ql.May, '06': ql.June,
            '07': ql.July, '08': ql.August, '09': ql.September,
            '10': ql.October, '11': ql.November, '12': ql.December
        }
        arr = re.findall(r"[\w']+", s)
        return ql.Date(int(arr[2]), monthDictionary[arr[1]], int(arr[0]))
    
    # convert string to QuantLib businessdayconvention enumerator
    def to_businessDayConvention(s):
        if (s.upper() == 'FOLLOWING'): return ql.Following
        if (s.upper() == 'MODIFIEDFOLLOWING'): return ql.ModifiedFollowing
        if (s.upper() == 'PRECEDING'): return ql.Preceding
        if (s.upper() == 'MODIFIEDPRECEDING'): return ql.ModifiedPreceding
        if (s.upper() == 'UNADJUSTED'): return ql.Unadjusted
        
    # convert string to QuantLib calendar object
    def to_calendar(s):
        if (s.upper() == 'TARGET'): return ql.TARGET()
        if (s.upper() == 'UNITEDSTATES'): return ql.UnitedStates()
        if (s.upper() == 'UNITEDKINGDOM'): return ql.UnitedKingdom()
        # TODO: add new calendar here
        
    # convert string to QuantLib swap type enumerator
    def to_swapType(s):
        if (s.upper() == 'PAYER'): return ql.VanillaSwap.Payer
        if (s.upper() == 'RECEIVER'): return ql.VanillaSwap.Receiver
        
    # convert string to QuantLib frequency enumerator
    def to_frequency(s):
        if (s.upper() == 'DAILY'): return ql.Daily
        if (s.upper() == 'WEEKLY'): return ql.Weekly
        if (s.upper() == 'MONTHLY'): return ql.Monthly
        if (s.upper() == 'QUARTERLY'): return ql.Quarterly
        if (s.upper() == 'SEMIANNUAL'): return ql.Semiannual
        if (s.upper() == 'ANNUAL'): return ql.Annual

    # convert string to QuantLib date generation rule enumerator
    def to_dateGenerationRule(s):
        if (s.upper() == 'BACKWARD'): return ql.DateGeneration.Backward
        if (s.upper() == 'FORWARD'): return ql.DateGeneration.Forward
        # TODO: add new date generation rule here

    # convert string to QuantLib day counter object
    def to_dayCounter(s):
        if (s.upper() == 'ACTUAL360'): return ql.Actual360()
        if (s.upper() == 'ACTUAL365FIXED'): return ql.Actual365Fixed()
        if (s.upper() == 'ACTUALACTUAL'): return ql.ActualActual()
        if (s.upper() == 'ACTUAL365NOLEAP'): return ql.Actual365NoLeap()
        if (s.upper() == 'BUSINESS252'): return ql.Business252()
        if (s.upper() == 'ONEDAYCOUNTER'): return ql.OneDayCounter()
        if (s.upper() == 'SIMPLEDAYCOUNTER'): return ql.SimpleDayCounter()
        if (s.upper() == 'THIRTY360'): return ql.Thirty360()
        
    # convert string (ex.'USDLibor.3M') to QuantLib ibor index object
    # note: forwarding term structure has to be linked to index object separately
    def to_iborIndex(s):
        s = s.split('.')
        if(s[0].upper() == 'USDLIBOR'): return ql.USDLibor(ql.Period(s[1]))
        if(s[0].upper() == 'EURIBOR'): return ql.Euribor(ql.Period(s[1]))  

class VanillaSwap(object):
    
    def __init__(self, ID, swapType, nominal, startDate, maturityDate, fixedLegFrequency, 
        fixedLegCalendar, fixedLegConvention, fixedLegDateGenerationRule, fixedLegRate, fixedLegDayCount,
        fixedLegEndOfMonth, floatingLegFrequency, floatingLegCalendar, floatingLegConvention, 
        floatingLegDateGenerationRule, floatingLegSpread, floatingLegDayCount, 
        floatingLegEndOfMonth, floatingLegIborIndex):

        # create member data, convert all required QuantLib types
        self.ID = str(ID)
        self.swapType = Convert.to_swapType(swapType)
        self.nominal = float(nominal)
        self.startDate = Convert.to_date(startDate)
        self.maturityDate = Convert.to_date(maturityDate)
        self.fixedLegFrequency = ql.Period(Convert.to_frequency(fixedLegFrequency))
        self.fixedLegCalendar = Convert.to_calendar(fixedLegCalendar)
        self.fixedLegConvention = Convert.to_businessDayConvention(fixedLegConvention)
        self.fixedLegDateGenerationRule = Convert.to_dateGenerationRule(fixedLegDateGenerationRule)
        self.fixedLegRate = float(fixedLegRate)
        self.fixedLegDayCount = Convert.to_dayCounter(fixedLegDayCount)
        self.fixedLegEndOfMonth = bool(fixedLegEndOfMonth)
        self.floatingLegFrequency = ql.Period(Convert.to_frequency(floatingLegFrequency))
        self.floatingLegCalendar = Convert.to_calendar(floatingLegCalendar)
        self.floatingLegConvention = Convert.to_businessDayConvention(floatingLegConvention)
        self.floatingLegDateGenerationRule = Convert.to_dateGenerationRule(floatingLegDateGenerationRule)
        self.floatingLegSpread = float(floatingLegSpread)
        self.floatingLegDayCount = Convert.to_dayCounter(floatingLegDayCount)
        self.floatingLegEndOfMonth = bool(floatingLegEndOfMonth)
        self.floatingLegIborIndex = Convert.to_iborIndex(floatingLegIborIndex)

        # create fixed leg schedule
        self.fixedLegSchedule = ql.Schedule(
            self.startDate, 
            self.maturityDate,
            self.fixedLegFrequency, 
            self.fixedLegCalendar, 
            self.fixedLegConvention,
            self.fixedLegConvention,
            self.fixedLegDateGenerationRule,
            self.fixedLegEndOfMonth)
        
        # create floating leg schedule
        self.floatingLegSchedule = ql.Schedule(
            self.startDate, 
            self.maturityDate,
            self.floatingLegFrequency, 
            self.floatingLegCalendar, 
            self.floatingLegConvention,
            self.floatingLegConvention,
            self.floatingLegDateGenerationRule,
            self.floatingLegEndOfMonth)

    # NPV method used for specific calibration purposes
    # x = list of forward rates
    # args: 0 = list of forward dates, 1 = list of market rates        
    def NPV_calibration(self, x, args):
        # concatenate given market rates and given forward rates
        x = np.concatenate([args[1], x])
        
        # create QuantLib yield term structure object
        # from a given set of forward rates and dates
        curve = ql.YieldTermStructureHandle(ql.ForwardCurve(args[0], x, 
            self.floatingLegDayCount, self.floatingLegCalendar))        

        # set forwarding term structure to floating leg index
        self.floatingLegIborIndex = self.floatingLegIborIndex.clone(curve) 
        
        # create vanilla interest rate swap
        self.instrument = ql.VanillaSwap(
            self.swapType, 
            self.nominal, 
            self.fixedLegSchedule, 
            self.fixedLegRate, 
            self.fixedLegDayCount, 
            self.floatingLegSchedule,
            self.floatingLegIborIndex,
            self.floatingLegSpread, 
            self.floatingLegDayCount)
        
        # pair instrument with pricing engine, request PV
        self.instrument.setPricingEngine(ql.DiscountingSwapEngine(curve))
        return self.instrument.NPV()
    
    # NPV method used for general pricing purposes
    def NPV(self, yieldTermStructureHandle, floatingLegIborIndex):
        # set forwarding term structure to floating leg index
        self.floatingLegIborIndex = floatingLegIborIndex.clone(yieldTermStructureHandle)
        
        # create vanilla interest rate swap
        self.instrument = ql.VanillaSwap(
            self.swapType, 
            self.nominal, 
            self.fixedLegSchedule, 
            self.fixedLegRate, 
            self.fixedLegDayCount, 
            self.floatingLegSchedule,
            self.floatingLegIborIndex,
            self.floatingLegSpread, 
            self.floatingLegDayCount)
        
        # pair instrument with pricing engine, request PV
        self.instrument.setPricingEngine(ql.DiscountingSwapEngine(yieldTermStructureHandle))
        return self.instrument.NPV()

ObjectiveFunction is used for minimization process for calculating sum of squared errors of all adjacent forward rates. Maximum smoothness of the curve will be achieved as a result of this minimization.

# objective function calculates sum of squared errors of all decision variables
# x = list of forward rates
# args: 0 = list of market rates data, 1 = scaling factor
def ObjectiveFunction(x, args):
    # concatenate given market rates and forward rates
    x = np.concatenate([args[0], x])
    return np.sum(np.power(np.diff(x), 2) * args[1])

The actual program flow will start by creating a set of vanilla interest rate swap objects (VanillaSwap) into list.

# dynamic data parts for set of vanilla swaps 
swapIDs = ['2Y', '3Y', '4Y', '5Y', '6Y', '7Y', '8Y', '9Y', '10Y', '12Y', '15Y', '20Y', '25Y', '30Y']
maturities = ['2010-02-08', '2011-02-07', '2012-02-06', '2013-02-06', '2014-02-06', '2015-02-06', '2016-02-08', 
    '2017-02-06', '2018-02-06', '2020-02-06', '2023-02-06', '2028-02-07', '2033-02-07', '2038-02-08']
swapRates = [0.02795, 0.03035, 0.03275, 0.03505, 0.03715, 0.03885, 0.04025, 0.04155, 0.04265, 0.04435, 
    0.04615, 0.04755, 0.04805, 0.04815]

# create vanilla swap transaction objects into list
swaps = [VanillaSwap(swapID, 'Payer', 1000000, '2008-02-06', maturity, 'Annual', 
    'Target', 'ModifiedFollowing', 'Backward', swapRate, 'Actual360', False, 'Quarterly', 
    'Target', 'ModifiedFollowing', 'Backward', 0.0, 'Actual360', False, 'USDLibor.3M')
    for swapID, maturity, swapRate in zip(swapIDs, maturities, swapRates)]

Next, the program will initialize the actual market data (to be used in forward curve), starting values for forward curve, set of dates for forward curve, optimization constraints and the actual optimization model.

# take initial forward rates from market data, set initial guesses and scaling factor for objective function
initialMarketData = np.array([0.03145, 0.0279275, 0.0253077, 0.0249374])
initialForwardGuesses = np.full(117, 0.02)
scalingFactor = 1000000.0

# create relevant QuantLib dates
today = ql.Date(4, 2, 2008)
ql.Settings.instance().evaluationDate = today  
settlementDate = ql.TARGET().advance(today, ql.Period(2, ql.Days))

# create set of dates for forward curve
dates = list(ql.Schedule(settlementDate, ql.Date(6, 2, 2038), ql.Period(ql.Quarterly), ql.TARGET(),
    ql.ModifiedFollowing, ql.ModifiedFollowing, ql.DateGeneration.Backward, False))

# create constraints for optimization model
swapConstraints = tuple([{'type': 'eq', 'fun': swap.NPV_calibration, 'args': [[dates, initialMarketData]]} for swap in swaps])

# create and execute scipy minimization model
model = opt.minimize(ObjectiveFunction, initialForwardGuesses, args = ([initialMarketData, scalingFactor]), 
    method = 'SLSQP', options = {'maxiter': 500}, constraints = swapConstraints)

After processing optimization model, the actual calibrated forward rates can be requested from the model. Next part of the program will just plot the calibrated forward term structure.

# extract calibrated forward rates, create times and plot term structure
forwards = np.concatenate([initialMarketData, model.x])
times = np.array([ql.Actual360().yearFraction(settlementDate, date) for date in dates])
pl.plot(times, forwards)
pl.show()


Final part of the program will create QuantLib yield term structure (QuantLib.ForwardCurve) and re-values our initial set of swap transactions. All swaps will be priced to zero at inception date.

# create new QuantLib curve from calibrated forward rates
curve = ql.YieldTermStructureHandle(ql.ForwardCurve(dates, forwards, ql.Actual360(), ql.TARGET()))

# value initial set of vanilla swaps using new QuantLib valuation curve
# all swaps will be priced to zero at inception date
for swap in swaps:
    index = ql.USDLibor(ql.Period(3, ql.Months), curve)
    pv = swap.NPV(curve, index)
    print(swap.ID, '{0:.5f}'.format(pv))

It should be noted, that by utilizing calibration scheme presented in this post, valuation curves (yield term structures) for QuantLib for all currencies and for all different basis can be constructed (assuming the relevant market data exists). Next logical step would be to implement similar scheme for calibrating valuation curves for QuantLib for cross-currency cases and within collateralized world.

Complete program can be downloaded from my GitHub page. Example data has been taken from chapter three within excellent book by Richard Flavell. Finally, thanks again for reading this blog.
-Mike

Sunday, July 14, 2019

QuantLib-Python: flexible construction scheme for piecewise yield term structures

I consider QuantLib to be a fundamental pricing library, which can effectively handle valuations for pretty much any given type of security. If there is no existing implementation for an instrument available, one can create a new implementation for it. What then makes the use of QuantLib library sometimes difficult? It's the amount of work to be done, before anything will happen. Outside of that promised functionality to value security, one has to take full responsibility of all involved janitor work. The code is (usually always) containing endless sections for different variable definitions and creation of different types of helper objects. Even creating realistic pricing scheme for a simple interest rate swap seems to require an army of different variables and objects. A lot of cooking anyway, before the beef will be served.

In this post, one possible scheme for flexible construction of QuantLib piecewise yield term structures will be presented. The program and all involved files can be downloaded from my GitHub repository.

Assume we would like to construct piecewise yield term structure for EUR and USD. Assume also, that we have the following market data for EUR and USD currencies in a specific CSV file.

Ticker,Value
USD.DEPOSIT.1D,0.02359
USD.DEPOSIT.1W,0.0237475
USD.DEPOSIT.1M,0.02325
USD.DEPOSIT.2M,0.0232475
USD.DEPOSIT.3M,0.0230338
USD.FUTURE.2M,97.92
USD.FUTURE.5M,98.005
USD.FUTURE.8M,98.185
USD.FUTURE.11M,98.27
USD.FUTURE.14M,98.33
USD.SWAP.2Y,0.01879
USD.SWAP.3Y,0.01835
USD.SWAP.5Y,0.01862
USD.SWAP.7Y,0.0194
USD.SWAP.10Y,0.02065
USD.SWAP.15Y,0.02204
USD.SWAP.30Y,0.02306
EUR.DEPOSIT.1D,-0.00366
EUR.DEPOSIT.1W,-0.00399
EUR.DEPOSIT.1M,-0.00393
EUR.DEPOSIT.3M,-0.00363
EUR.DEPOSIT.6M,-0.00342
EUR.FUTURE.5M,100.48
EUR.FUTURE.8M,100.505
EUR.FUTURE.11M,100.505
EUR.FUTURE.14M,100.495
EUR.FUTURE.17M,100.47
EUR.SWAP.1Y,-0.0038
EUR.SWAP.2Y,-0.0039
EUR.SWAP.5Y,-0.0019
EUR.SWAP.7Y,-0.0002
EUR.SWAP.10Y,0.0024
EUR.SWAP.15Y,0.0056
EUR.SWAP.30Y,0.008

In essence, we have key-value pairs in this CSV file, where the key is ticker (instrument, such as deposit, future or swap) and the value is rate (or price for a futures contract). Now, all instruments in that file are following some specific market conventions. All these conventions are then stored in a specific JSON file. The content of this file can be easily understood by using some available JSON editor.


In essence, we are actually storing all required "constant" parameters for all QuantLib instruments we would like to use for constructing piecewise yield curves, into this file. At the moment, there are required conventions available for constructing EUR and USD curves.

Next, we have builder class PiecewiseCurveBuilder for assembling QuantLib piecewise yield term structures, as shown below. In the first stage, we store all conventions and market data into this builder class in its constructor. After this, builder is ready for constructing curves. As client is requesting specific curve by using Build method, the class will then create all bootstrap helpers based on a given market data (for requested currency) and instrument conventions (for instruments in requested currency).

# create piecewise yield term structure
class PiecewiseCurveBuilder(object):
    
    # in constructor, we store all possible instrument conventions and market data
    def __init__(self, settlementDate, conventions, marketData):        
        self.helpers = [] # list containing bootstrap helpers
        self.settlementDate = settlementDate
        self.conventions = conventions
        self.market = marketData
    
    # for a given currency, first assemble bootstrap helpers, 
    # then construct yield term structure handle
    def Build(self, currency, enableExtrapolation = True):

        # clear all existing bootstrap helpers from list
        self.helpers.clear()
        # filter out correct market data set for a given currency
        data = self.market.loc[self.market['Ticker'].str.contains(currency), :]
        
        # loop through market data set
        for i in range(data.shape[0]):            
            # extract ticker and value
            ticker = data.iloc[i]['Ticker']
            value = data.iloc[i]['Value'] 
            
            # add deposit rate helper
            # ticker prototype: 'CCY.DEPOSIT.3M'
            if('DEPOSIT' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['DEPOSIT']
                rate = value
                period = ql.Period(ticker.split('.')[2])
                # extract parameters from instrument convention
                fixingDays = convention['FIXINGDAYS']
                calendar = Convert.to_calendar(convention['CALENDAR'])
                businessDayConvention = Convert.to_businessDayConvention(convention['BUSINESSDAYCONVENTION'])
                endOfMonth = convention['ENDOFMONTH']
                dayCounter = Convert.to_dayCounter(convention['DAYCOUNTER'])
                # create and append deposit helper into helper list
                self.helpers.append(ql.DepositRateHelper(rate, period, fixingDays, 
                    calendar, businessDayConvention, endOfMonth, dayCounter))
        
            # add futures rate helper
            # ticker prototype: 'CCY.FUTURE.10M'
            # note: third ticker field ('10M') is defining starting date
            # for future to be 10 months after defined settlement date
            if('FUTURE' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['FUTURE']
                price = value
                iborStartDate = ql.IMM.nextDate(self.settlementDate + ql.Period(ticker.split('.')[2]))
                # extract parameters from instrument convention
                lengthInMonths = convention['LENGTHINMONTHS']
                calendar = Convert.to_calendar(convention['CALENDAR'])
                businessDayConvention = Convert.to_businessDayConvention(convention['BUSINESSDAYCONVENTION']) 
                endOfMonth = convention['ENDOFMONTH']
                dayCounter = Convert.to_dayCounter(convention['DAYCOUNTER'])
                # create and append futures helper into helper list
                self.helpers.append(ql.FuturesRateHelper(price, iborStartDate, lengthInMonths,
                    calendar, businessDayConvention, endOfMonth, dayCounter))                
            
            # add swap rate helper
            # ticker prototype: 'CCY.SWAP.2Y'
            if('SWAP' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['SWAP']
                rate = value
                periodLength = ql.Period(ticker.split('.')[2])
                # extract parameters from instrument convention
                fixedCalendar = Convert.to_calendar(convention['FIXEDCALENDAR'])
                fixedFrequency = Convert.to_frequency(convention['FIXEDFREQUENCY']) 
                fixedConvention = Convert.to_businessDayConvention(convention['FIXEDCONVENTION'])
                fixedDayCount = Convert.to_dayCounter(convention['FIXEDDAYCOUNTER'])
                floatIndex = Convert.to_iborIndex(convention['FLOATINDEX']) 
                # create and append swap helper into helper list
                self.helpers.append(ql.SwapRateHelper(rate, periodLength, fixedCalendar,
                    fixedFrequency, fixedConvention, fixedDayCount, floatIndex))
        
        # extract day counter for curve from configurations
        dayCounter = Convert.to_dayCounter(self.conventions[currency]['CONFIGURATIONS']['DAYCOUNTER'])
        # construct yield term structure handle
        yieldTermStructure = ql.PiecewiseLinearZero(self.settlementDate, self.helpers, dayCounter)
        if(enableExtrapolation == True): yieldTermStructure.enableExtrapolation()
        return ql.RelinkableYieldTermStructureHandle(yieldTermStructure)

The final component in this scheme is Convert class, which performs conversions from string presentation to specific QuantLib data types. This class is heavily used in builder class, where convention string information is transformed into correct QuantLib data types.

# utility class for different QuantLib type conversions 
class Convert:
    
    # convert date string ('yyyy-mm-dd') to QuantLib Date object
    def to_date(s):
        monthDictionary = {
            '01': ql.January, '02': ql.February, '03': ql.March,
            '04': ql.April, '05': ql.May, '06': ql.June,
            '07': ql.July, '08': ql.August, '09': ql.September,
            '10': ql.October, '11': ql.November, '12': ql.December
        }
        s = s.split('-')
        return ql.Date(int(s[2]), monthDictionary[s[1]], int(s[0]))
    
    # convert string to QuantLib businessdayconvention enumerator
    def to_businessDayConvention(s):
        if (s.upper() == 'FOLLOWING'): return ql.Following
        if (s.upper() == 'MODIFIEDFOLLOWING'): return ql.ModifiedFollowing
        if (s.upper() == 'PRECEDING'): return ql.Preceding
        if (s.upper() == 'MODIFIEDPRECEDING'): return ql.ModifiedPreceding
        if (s.upper() == 'UNADJUSTED'): return ql.Unadjusted
        
    # convert string to QuantLib calendar object
    def to_calendar(s):
        if (s.upper() == 'TARGET'): return ql.TARGET()
        if (s.upper() == 'UNITEDSTATES'): return ql.UnitedStates()
        if (s.upper() == 'UNITEDKINGDOM'): return ql.UnitedKingdom()
        # TODO: add new calendar here
        
    # convert string to QuantLib swap type enumerator
    def to_swapType(s):
        if (s.upper() == 'PAYER'): return ql.VanillaSwap.Payer
        if (s.upper() == 'RECEIVER'): return ql.VanillaSwap.Receiver
        
    # convert string to QuantLib frequency enumerator
    def to_frequency(s):
        if (s.upper() == 'DAILY'): return ql.Daily
        if (s.upper() == 'WEEKLY'): return ql.Weekly
        if (s.upper() == 'MONTHLY'): return ql.Monthly
        if (s.upper() == 'QUARTERLY'): return ql.Quarterly
        if (s.upper() == 'SEMIANNUAL'): return ql.Semiannual
        if (s.upper() == 'ANNUAL'): return ql.Annual

    # convert string to QuantLib date generation rule enumerator
    def to_dateGenerationRule(s):
        if (s.upper() == 'BACKWARD'): return ql.DateGeneration.Backward
        if (s.upper() == 'FORWARD'): return ql.DateGeneration.Forward
        # TODO: add new date generation rule here

    # convert string to QuantLib day counter object
    def to_dayCounter(s):
        if (s.upper() == 'ACTUAL360'): return ql.Actual360()
        if (s.upper() == 'ACTUAL365FIXED'): return ql.Actual365Fixed()
        if (s.upper() == 'ACTUALACTUAL'): return ql.ActualActual()
        if (s.upper() == 'ACTUAL365NOLEAP'): return ql.Actual365NoLeap()
        if (s.upper() == 'BUSINESS252'): return ql.Business252()
        if (s.upper() == 'ONEDAYCOUNTER'): return ql.OneDayCounter()
        if (s.upper() == 'SIMPLEDAYCOUNTER'): return ql.SimpleDayCounter()
        if (s.upper() == 'THIRTY360'): return ql.Thirty360()

    # convert string (ex.'USD.3M') to QuantLib ibor index object
    def to_iborIndex(s):
        s = s.split('.')
        if(s[0].upper() == 'USD'): return ql.USDLibor(ql.Period(s[1]))
        if(s[0].upper() == 'EUR'): return ql.Euribor(ql.Period(s[1]))        

Finally, let us take a look, how easily we can actually construct QuantLib piecewise yield term structures for our two currencies. After this point, these constructed curves can then be used as arguments for pricing engines.

# create instrument conventions and market data
rootDirectory = sys.argv[1] # command line argument: '/home/mikejuniperhill/QuantLib/'
evaluationDate = Convert.to_date(datetime.today().strftime('%Y-%m-%d'))
ql.Settings.instance().evaluationDate = evaluationDate
conventions = Configurations(rootDirectory + 'conventions.json')
marketData = pd.read_csv(rootDirectory + 'marketdata.csv')

# initialize builder, store all conventions and market data
builder = PiecewiseCurveBuilder(evaluationDate, conventions, marketData)
currencies = sys.argv[2] # command line argument: 'USD,EUR'
currencies = currencies.split(',')

# construct curves based on instrument conventions, given market data and currencies
for currency in currencies:    
    curve = builder.Build(currency)
    # print discount factors semiannually up to 30 years
    times = np.linspace(0.0, 30.0, 61)
    df = [round(curve.discount(t), 4) for t in times]
    print('discount factors for', currency)
    print(df)

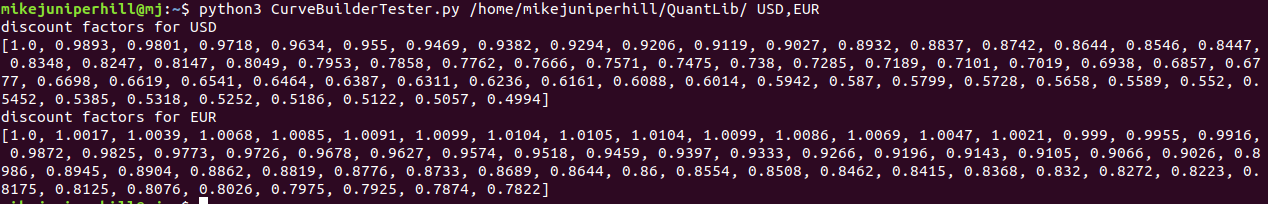
Address to root directory (containing market data and instrument conventions files) and requested currencies are given as command line arguments. Conventions object and market data (pandas data frame) are being created and fed to curve builder object in its constructor. Finally, curves are being requested for each currency.

It can be seen, that we can actually create piecewise yield term structures for any currency (as long as market data and conventions are available) with a very few lines of code by using this kind of construction scheme. In essence, all the complexity involved is still there, but we have effectively moved all "janitor work" into specific classes (builder, conversions) and files (conventions, market data).

Configuration for a new currency should be straightforward: add instruments into market data file (ticker-value-pairs). Then, add new section for this new currency to conventions file (including configuration sub-sections for all instruments in this new currency). Also, some minor additions might be needed in conversion class.

Program execution is shown below.


Thanks for reading my blog.
-Mike