In this post, one possible scheme for flexible construction of QuantLib piecewise yield term structures will be presented. The program and all involved files can be downloaded from my GitHub repository.
Assume we would like to construct piecewise yield term structure for EUR and USD. Assume also, that we have the following market data for EUR and USD currencies in a specific CSV file.
Ticker,Value
USD.DEPOSIT.1D,0.02359
USD.DEPOSIT.1W,0.0237475
USD.DEPOSIT.1M,0.02325
USD.DEPOSIT.2M,0.0232475
USD.DEPOSIT.3M,0.0230338
USD.FUTURE.2M,97.92
USD.FUTURE.5M,98.005
USD.FUTURE.8M,98.185
USD.FUTURE.11M,98.27
USD.FUTURE.14M,98.33
USD.SWAP.2Y,0.01879
USD.SWAP.3Y,0.01835
USD.SWAP.5Y,0.01862
USD.SWAP.7Y,0.0194
USD.SWAP.10Y,0.02065
USD.SWAP.15Y,0.02204
USD.SWAP.30Y,0.02306
EUR.DEPOSIT.1D,-0.00366
EUR.DEPOSIT.1W,-0.00399
EUR.DEPOSIT.1M,-0.00393
EUR.DEPOSIT.3M,-0.00363
EUR.DEPOSIT.6M,-0.00342
EUR.FUTURE.5M,100.48
EUR.FUTURE.8M,100.505
EUR.FUTURE.11M,100.505
EUR.FUTURE.14M,100.495
EUR.FUTURE.17M,100.47
EUR.SWAP.1Y,-0.0038
EUR.SWAP.2Y,-0.0039
EUR.SWAP.5Y,-0.0019
EUR.SWAP.7Y,-0.0002
EUR.SWAP.10Y,0.0024
EUR.SWAP.15Y,0.0056
EUR.SWAP.30Y,0.008
In essence, we have key-value pairs in this CSV file, where the key is ticker (instrument, such as deposit, future or swap) and the value is rate (or price for a futures contract). Now, all instruments in that file are following some specific market conventions. All these conventions are then stored in a specific JSON file. The content of this file can be easily understood by using some available JSON editor.

In essence, we are actually storing all required "constant" parameters for all QuantLib instruments we would like to use for constructing piecewise yield curves, into this file. At the moment, there are required conventions available for constructing EUR and USD curves.
Next, we have builder class PiecewiseCurveBuilder for assembling QuantLib piecewise yield term structures, as shown below. In the first stage, we store all conventions and market data into this builder class in its constructor. After this, builder is ready for constructing curves. As client is requesting specific curve by using Build method, the class will then create all bootstrap helpers based on a given market data (for requested currency) and instrument conventions (for instruments in requested currency).
# create piecewise yield term structure
class PiecewiseCurveBuilder(object):

    # in constructor, we store all possible instrument conventions and market data
    def __init__(self, settlementDate, conventions, marketData):
        self.helpers = [] # list containing bootstrap helpers
        self.settlementDate = settlementDate
        self.conventions = conventions
        self.market = marketData

    # for a given currency, first assemble bootstrap helpers,
    # then construct yield term structure handle
    def Build(self, currency, enableExtrapolation = True):

        # clear all existing bootstrap helpers from list
        self.helpers.clear()
        # filter out correct market data set for a given currency
        data = self.market.loc[self.market['Ticker'].str.contains(currency), :]

        # loop through market data set
        for i in range(data.shape[0]):
            # extract ticker and value
            ticker = data.iloc[i]['Ticker']
            value = data.iloc[i]['Value']

            # add deposit rate helper
            # ticker prototype: 'CCY.DEPOSIT.3M'
            if('DEPOSIT' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['DEPOSIT']
                rate = value
                period = ql.Period(ticker.split('.')[2])
                # extract parameters from instrument convention
                fixingDays = convention['FIXINGDAYS']
                calendar = Convert.to_calendar(convention['CALENDAR'])
                businessDayConvention = Convert.to_businessDayConvention(convention['BUSINESSDAYCONVENTION'])
                endOfMonth = convention['ENDOFMONTH']
                dayCounter = Convert.to_dayCounter(convention['DAYCOUNTER'])
                # create and append deposit helper into helper list
                self.helpers.append(ql.DepositRateHelper(rate, period, fixingDays,
                    calendar, businessDayConvention, endOfMonth, dayCounter))

            # add futures rate helper
            # ticker prototype: 'CCY.FUTURE.10M'
            # note: third ticker field ('10M') is defining starting date
            # for future to be 10 months after defined settlement date
            if('FUTURE' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['FUTURE']
                price = value
                iborStartDate = ql.IMM.nextDate(self.settlementDate + ql.Period(ticker.split('.')[2]))
                # extract parameters from instrument convention
                lengthInMonths = convention['LENGTHINMONTHS']
                calendar = Convert.to_calendar(convention['CALENDAR'])
                businessDayConvention = Convert.to_businessDayConvention(convention['BUSINESSDAYCONVENTION'])
                endOfMonth = convention['ENDOFMONTH']
                dayCounter = Convert.to_dayCounter(convention['DAYCOUNTER'])
                # create and append futures helper into helper list
                self.helpers.append(ql.FuturesRateHelper(price, iborStartDate, lengthInMonths,
                    calendar, businessDayConvention, endOfMonth, dayCounter))

            # add swap rate helper
            # ticker prototype: 'CCY.SWAP.2Y'
            if('SWAP' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['SWAP']
                rate = value
                periodLength = ql.Period(ticker.split('.')[2])
                # extract parameters from instrument convention
                fixedCalendar = Convert.to_calendar(convention['FIXEDCALENDAR'])
                fixedFrequency = Convert.to_frequency(convention['FIXEDFREQUENCY'])
                fixedConvention = Convert.to_businessDayConvention(convention['FIXEDCONVENTION'])
                fixedDayCount = Convert.to_dayCounter(convention['FIXEDDAYCOUNTER'])
                floatIndex = Convert.to_iborIndex(convention['FLOATINDEX'])
                # create and append swap helper into helper list
                self.helpers.append(ql.SwapRateHelper(rate, periodLength, fixedCalendar,
                    fixedFrequency, fixedConvention, fixedDayCount, floatIndex))

        # extract day counter for curve from configurations
        dayCounter = Convert.to_dayCounter(self.conventions[currency]['CONFIGURATIONS']['DAYCOUNTER'])
        # construct yield term structure handle
        yieldTermStructure = ql.PiecewiseLinearZero(self.settlementDate, self.helpers, dayCounter)
        if(enableExtrapolation == True): yieldTermStructure.enableExtrapolation()
        return ql.RelinkableYieldTermStructureHandle(yieldTermStructure)
The final component in this scheme is Convert class, which performs conversions from string presentation to specific QuantLib data types. This class is heavily used in builder class, where convention string information is transformed into correct QuantLib data types.
# utility class for different QuantLib type conversions
class Convert:

    # convert date string ('yyyy-mm-dd') to QuantLib Date object
    def to_date(s):
        monthDictionary = {
            '01': ql.January, '02': ql.February, '03': ql.March,
            '04': ql.April, '05': ql.May, '06': ql.June,
            '07': ql.July, '08': ql.August, '09': ql.September,
            '10': ql.October, '11': ql.November, '12': ql.December
        }
        s = s.split('-')
        return ql.Date(int(s[2]), monthDictionary[s[1]], int(s[0]))

    # convert string to QuantLib businessdayconvention enumerator
    def to_businessDayConvention(s):
        if (s.upper() == 'FOLLOWING'): return ql.Following
        if (s.upper() == 'MODIFIEDFOLLOWING'): return ql.ModifiedFollowing
        if (s.upper() == 'PRECEDING'): return ql.Preceding
        if (s.upper() == 'MODIFIEDPRECEDING'): return ql.ModifiedPreceding
        if (s.upper() == 'UNADJUSTED'): return ql.Unadjusted

    # convert string to QuantLib calendar object
    def to_calendar(s):
        if (s.upper() == 'TARGET'): return ql.TARGET()
        if (s.upper() == 'UNITEDSTATES'): return ql.UnitedStates()
        if (s.upper() == 'UNITEDKINGDOM'): return ql.UnitedKingdom()
        # TODO: add new calendar here

    # convert string to QuantLib swap type enumerator
    def to_swapType(s):
        if (s.upper() == 'PAYER'): return ql.VanillaSwap.Payer
        if (s.upper() == 'RECEIVER'): return ql.VanillaSwap.Receiver

    # convert string to QuantLib frequency enumerator
    def to_frequency(s):
        if (s.upper() == 'DAILY'): return ql.Daily
        if (s.upper() == 'WEEKLY'): return ql.Weekly
        if (s.upper() == 'MONTHLY'): return ql.Monthly
        if (s.upper() == 'QUARTERLY'): return ql.Quarterly
        if (s.upper() == 'SEMIANNUAL'): return ql.Semiannual
        if (s.upper() == 'ANNUAL'): return ql.Annual

    # convert string to QuantLib date generation rule enumerator
    def to_dateGenerationRule(s):
        if (s.upper() == 'BACKWARD'): return ql.DateGeneration.Backward
        if (s.upper() == 'FORWARD'): return ql.DateGeneration.Forward
        # TODO: add new date generation rule here

    # convert string to QuantLib day counter object
    def to_dayCounter(s):
        if (s.upper() == 'ACTUAL360'): return ql.Actual360()
        if (s.upper() == 'ACTUAL365FIXED'): return ql.Actual365Fixed()
        if (s.upper() == 'ACTUALACTUAL'): return ql.ActualActual()
        if (s.upper() == 'ACTUAL365NOLEAP'): return ql.Actual365NoLeap()
        if (s.upper() == 'BUSINESS252'): return ql.Business252()
        if (s.upper() == 'ONEDAYCOUNTER'): return ql.OneDayCounter()
        if (s.upper() == 'SIMPLEDAYCOUNTER'): return ql.SimpleDayCounter()
        if (s.upper() == 'THIRTY360'): return ql.Thirty360()

    # convert string (ex.'USD.3M') to QuantLib ibor index object
    def to_iborIndex(s):
        s = s.split('.')
        if(s[0].upper() == 'USD'): return ql.USDLibor(ql.Period(s[1]))
        if(s[0].upper() == 'EUR'): return ql.Euribor(ql.Period(s[1]))
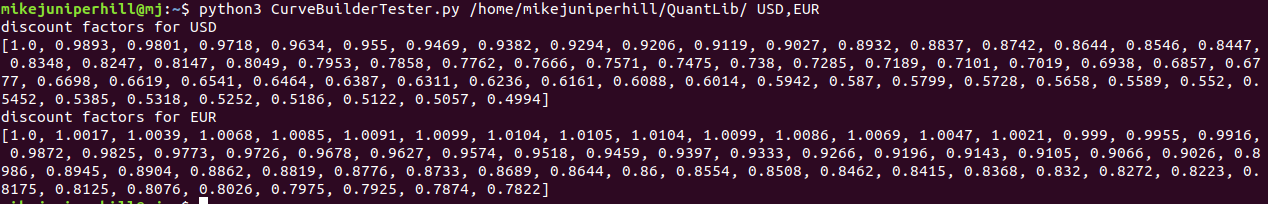
Finally, let us take a look, how easily we can actually construct QuantLib piecewise yield term structures for our two currencies. After this point, these constructed curves can then be used as arguments for pricing engines.
# create instrument conventions and market data
rootDirectory = sys.argv[1] # command line argument: '/home/mikejuniperhill/QuantLib/'
evaluationDate = Convert.to_date(datetime.today().strftime('%Y-%m-%d'))
ql.Settings.instance().evaluationDate = evaluationDate
conventions = Configurations(rootDirectory + 'conventions.json')
marketData = pd.read_csv(rootDirectory + 'marketdata.csv')

# initialize builder, store all conventions and market data
builder = PiecewiseCurveBuilder(evaluationDate, conventions, marketData)
currencies = sys.argv[2] # command line argument: 'USD,EUR'
currencies = currencies.split(',')

# construct curves based on instrument conventions, given market data and currencies
for currency in currencies:
    curve = builder.Build(currency)
    # print discount factors semiannually up to 30 years
    times = np.linspace(0.0, 30.0, 61)
    df = [round(curve.discount(t), 4) for t in times]
    print('discount factors for', currency)
    print(df)
Address to root directory (containing market data and instrument conventions files) and requested currencies are given as command line arguments. Conventions object and market data (pandas data frame) are being created and fed to curve builder object in its constructor. Finally, curves are being requested for each currency.
It can be seen, that we can actually create piecewise yield term structures for any currency (as long as market data and conventions are available) with a very few lines of code by using this kind of construction scheme. In essence, all the complexity involved is still there, but we have effectively moved all "janitor work" into specific classes (builder, conversions) and files (conventions, market data).
Configuration for a new currency should be straightforward: add instruments into market data file (ticker-value-pairs). Then, add new section for this new currency to conventions file (including configuration sub-sections for all instruments in this new currency). Also, some minor additions might be needed in conversion class.
Program execution is shown below.
Thanks for reading my blog.
-Mike

