Sunday, July 14, 2019

QuantLib-Python: flexible construction scheme for piecewise yield term structures

I consider QuantLib to be a fundamental pricing library, which can effectively handle valuations for pretty much any given type of security. If there is no existing implementation for an instrument available, one can create a new implementation for it. What then makes the use of QuantLib library sometimes difficult? It's the amount of work to be done, before anything will happen. Outside of that promised functionality to value security, one has to take full responsibility of all involved janitor work. The code is (usually always) containing endless sections for different variable definitions and creation of different types of helper objects. Even creating realistic pricing scheme for a simple interest rate swap seems to require an army of different variables and objects. A lot of cooking anyway, before the beef will be served.

In this post, one possible scheme for flexible construction of QuantLib piecewise yield term structures will be presented. The program and all involved files can be downloaded from my GitHub repository.

Assume we would like to construct piecewise yield term structure for EUR and USD. Assume also, that we have the following market data for EUR and USD currencies in a specific CSV file.

Ticker,Value
USD.DEPOSIT.1D,0.02359
USD.DEPOSIT.1W,0.0237475
USD.DEPOSIT.1M,0.02325
USD.DEPOSIT.2M,0.0232475
USD.DEPOSIT.3M,0.0230338
USD.FUTURE.2M,97.92
USD.FUTURE.5M,98.005
USD.FUTURE.8M,98.185
USD.FUTURE.11M,98.27
USD.FUTURE.14M,98.33
USD.SWAP.2Y,0.01879
USD.SWAP.3Y,0.01835
USD.SWAP.5Y,0.01862
USD.SWAP.7Y,0.0194
USD.SWAP.10Y,0.02065
USD.SWAP.15Y,0.02204
USD.SWAP.30Y,0.02306
EUR.DEPOSIT.1D,-0.00366
EUR.DEPOSIT.1W,-0.00399
EUR.DEPOSIT.1M,-0.00393
EUR.DEPOSIT.3M,-0.00363
EUR.DEPOSIT.6M,-0.00342
EUR.FUTURE.5M,100.48
EUR.FUTURE.8M,100.505
EUR.FUTURE.11M,100.505
EUR.FUTURE.14M,100.495
EUR.FUTURE.17M,100.47
EUR.SWAP.1Y,-0.0038
EUR.SWAP.2Y,-0.0039
EUR.SWAP.5Y,-0.0019
EUR.SWAP.7Y,-0.0002
EUR.SWAP.10Y,0.0024
EUR.SWAP.15Y,0.0056
EUR.SWAP.30Y,0.008

In essence, we have key-value pairs in this CSV file, where the key is ticker (instrument, such as deposit, future or swap) and the value is rate (or price for a futures contract). Now, all instruments in that file are following some specific market conventions. All these conventions are then stored in a specific JSON file. The content of this file can be easily understood by using some available JSON editor.


In essence, we are actually storing all required "constant" parameters for all QuantLib instruments we would like to use for constructing piecewise yield curves, into this file. At the moment, there are required conventions available for constructing EUR and USD curves.

Next, we have builder class PiecewiseCurveBuilder for assembling QuantLib piecewise yield term structures, as shown below. In the first stage, we store all conventions and market data into this builder class in its constructor. After this, builder is ready for constructing curves. As client is requesting specific curve by using Build method, the class will then create all bootstrap helpers based on a given market data (for requested currency) and instrument conventions (for instruments in requested currency).

# create piecewise yield term structure
class PiecewiseCurveBuilder(object):
    
    # in constructor, we store all possible instrument conventions and market data
    def __init__(self, settlementDate, conventions, marketData):        
        self.helpers = [] # list containing bootstrap helpers
        self.settlementDate = settlementDate
        self.conventions = conventions
        self.market = marketData
    
    # for a given currency, first assemble bootstrap helpers, 
    # then construct yield term structure handle
    def Build(self, currency, enableExtrapolation = True):

        # clear all existing bootstrap helpers from list
        self.helpers.clear()
        # filter out correct market data set for a given currency
        data = self.market.loc[self.market['Ticker'].str.contains(currency), :]
        
        # loop through market data set
        for i in range(data.shape[0]):            
            # extract ticker and value
            ticker = data.iloc[i]['Ticker']
            value = data.iloc[i]['Value'] 
            
            # add deposit rate helper
            # ticker prototype: 'CCY.DEPOSIT.3M'
            if('DEPOSIT' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['DEPOSIT']
                rate = value
                period = ql.Period(ticker.split('.')[2])
                # extract parameters from instrument convention
                fixingDays = convention['FIXINGDAYS']
                calendar = Convert.to_calendar(convention['CALENDAR'])
                businessDayConvention = Convert.to_businessDayConvention(convention['BUSINESSDAYCONVENTION'])
                endOfMonth = convention['ENDOFMONTH']
                dayCounter = Convert.to_dayCounter(convention['DAYCOUNTER'])
                # create and append deposit helper into helper list
                self.helpers.append(ql.DepositRateHelper(rate, period, fixingDays, 
                    calendar, businessDayConvention, endOfMonth, dayCounter))
        
            # add futures rate helper
            # ticker prototype: 'CCY.FUTURE.10M'
            # note: third ticker field ('10M') is defining starting date
            # for future to be 10 months after defined settlement date
            if('FUTURE' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['FUTURE']
                price = value
                iborStartDate = ql.IMM.nextDate(self.settlementDate + ql.Period(ticker.split('.')[2]))
                # extract parameters from instrument convention
                lengthInMonths = convention['LENGTHINMONTHS']
                calendar = Convert.to_calendar(convention['CALENDAR'])
                businessDayConvention = Convert.to_businessDayConvention(convention['BUSINESSDAYCONVENTION']) 
                endOfMonth = convention['ENDOFMONTH']
                dayCounter = Convert.to_dayCounter(convention['DAYCOUNTER'])
                # create and append futures helper into helper list
                self.helpers.append(ql.FuturesRateHelper(price, iborStartDate, lengthInMonths,
                    calendar, businessDayConvention, endOfMonth, dayCounter))                
            
            # add swap rate helper
            # ticker prototype: 'CCY.SWAP.2Y'
            if('SWAP' in ticker):
                # extract correct instrument convention
                convention = self.conventions[currency]['SWAP']
                rate = value
                periodLength = ql.Period(ticker.split('.')[2])
                # extract parameters from instrument convention
                fixedCalendar = Convert.to_calendar(convention['FIXEDCALENDAR'])
                fixedFrequency = Convert.to_frequency(convention['FIXEDFREQUENCY']) 
                fixedConvention = Convert.to_businessDayConvention(convention['FIXEDCONVENTION'])
                fixedDayCount = Convert.to_dayCounter(convention['FIXEDDAYCOUNTER'])
                floatIndex = Convert.to_iborIndex(convention['FLOATINDEX']) 
                # create and append swap helper into helper list
                self.helpers.append(ql.SwapRateHelper(rate, periodLength, fixedCalendar,
                    fixedFrequency, fixedConvention, fixedDayCount, floatIndex))
        
        # extract day counter for curve from configurations
        dayCounter = Convert.to_dayCounter(self.conventions[currency]['CONFIGURATIONS']['DAYCOUNTER'])
        # construct yield term structure handle
        yieldTermStructure = ql.PiecewiseLinearZero(self.settlementDate, self.helpers, dayCounter)
        if(enableExtrapolation == True): yieldTermStructure.enableExtrapolation()
        return ql.RelinkableYieldTermStructureHandle(yieldTermStructure)

The final component in this scheme is Convert class, which performs conversions from string presentation to specific QuantLib data types. This class is heavily used in builder class, where convention string information is transformed into correct QuantLib data types.

# utility class for different QuantLib type conversions 
class Convert:
    
    # convert date string ('yyyy-mm-dd') to QuantLib Date object
    def to_date(s):
        monthDictionary = {
            '01': ql.January, '02': ql.February, '03': ql.March,
            '04': ql.April, '05': ql.May, '06': ql.June,
            '07': ql.July, '08': ql.August, '09': ql.September,
            '10': ql.October, '11': ql.November, '12': ql.December
        }
        s = s.split('-')
        return ql.Date(int(s[2]), monthDictionary[s[1]], int(s[0]))
    
    # convert string to QuantLib businessdayconvention enumerator
    def to_businessDayConvention(s):
        if (s.upper() == 'FOLLOWING'): return ql.Following
        if (s.upper() == 'MODIFIEDFOLLOWING'): return ql.ModifiedFollowing
        if (s.upper() == 'PRECEDING'): return ql.Preceding
        if (s.upper() == 'MODIFIEDPRECEDING'): return ql.ModifiedPreceding
        if (s.upper() == 'UNADJUSTED'): return ql.Unadjusted
        
    # convert string to QuantLib calendar object
    def to_calendar(s):
        if (s.upper() == 'TARGET'): return ql.TARGET()
        if (s.upper() == 'UNITEDSTATES'): return ql.UnitedStates()
        if (s.upper() == 'UNITEDKINGDOM'): return ql.UnitedKingdom()
        # TODO: add new calendar here
        
    # convert string to QuantLib swap type enumerator
    def to_swapType(s):
        if (s.upper() == 'PAYER'): return ql.VanillaSwap.Payer
        if (s.upper() == 'RECEIVER'): return ql.VanillaSwap.Receiver
        
    # convert string to QuantLib frequency enumerator
    def to_frequency(s):
        if (s.upper() == 'DAILY'): return ql.Daily
        if (s.upper() == 'WEEKLY'): return ql.Weekly
        if (s.upper() == 'MONTHLY'): return ql.Monthly
        if (s.upper() == 'QUARTERLY'): return ql.Quarterly
        if (s.upper() == 'SEMIANNUAL'): return ql.Semiannual
        if (s.upper() == 'ANNUAL'): return ql.Annual

    # convert string to QuantLib date generation rule enumerator
    def to_dateGenerationRule(s):
        if (s.upper() == 'BACKWARD'): return ql.DateGeneration.Backward
        if (s.upper() == 'FORWARD'): return ql.DateGeneration.Forward
        # TODO: add new date generation rule here

    # convert string to QuantLib day counter object
    def to_dayCounter(s):
        if (s.upper() == 'ACTUAL360'): return ql.Actual360()
        if (s.upper() == 'ACTUAL365FIXED'): return ql.Actual365Fixed()
        if (s.upper() == 'ACTUALACTUAL'): return ql.ActualActual()
        if (s.upper() == 'ACTUAL365NOLEAP'): return ql.Actual365NoLeap()
        if (s.upper() == 'BUSINESS252'): return ql.Business252()
        if (s.upper() == 'ONEDAYCOUNTER'): return ql.OneDayCounter()
        if (s.upper() == 'SIMPLEDAYCOUNTER'): return ql.SimpleDayCounter()
        if (s.upper() == 'THIRTY360'): return ql.Thirty360()

    # convert string (ex.'USD.3M') to QuantLib ibor index object
    def to_iborIndex(s):
        s = s.split('.')
        if(s[0].upper() == 'USD'): return ql.USDLibor(ql.Period(s[1]))
        if(s[0].upper() == 'EUR'): return ql.Euribor(ql.Period(s[1]))        

Finally, let us take a look, how easily we can actually construct QuantLib piecewise yield term structures for our two currencies. After this point, these constructed curves can then be used as arguments for pricing engines.

# create instrument conventions and market data
rootDirectory = sys.argv[1] # command line argument: '/home/mikejuniperhill/QuantLib/'
evaluationDate = Convert.to_date(datetime.today().strftime('%Y-%m-%d'))
ql.Settings.instance().evaluationDate = evaluationDate
conventions = Configurations(rootDirectory + 'conventions.json')
marketData = pd.read_csv(rootDirectory + 'marketdata.csv')

# initialize builder, store all conventions and market data
builder = PiecewiseCurveBuilder(evaluationDate, conventions, marketData)
currencies = sys.argv[2] # command line argument: 'USD,EUR'
currencies = currencies.split(',')

# construct curves based on instrument conventions, given market data and currencies
for currency in currencies:    
    curve = builder.Build(currency)
    # print discount factors semiannually up to 30 years
    times = np.linspace(0.0, 30.0, 61)
    df = [round(curve.discount(t), 4) for t in times]
    print('discount factors for', currency)
    print(df)

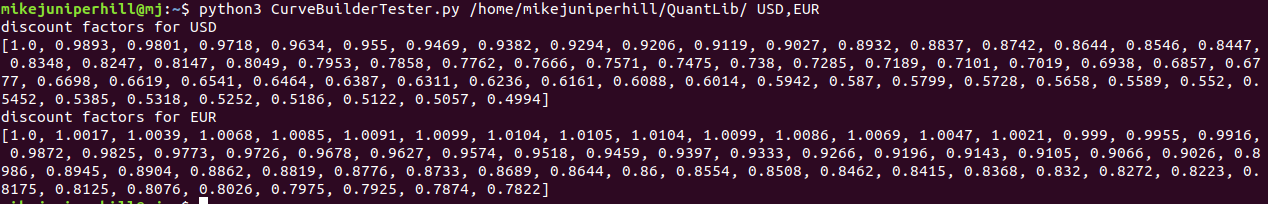
Address to root directory (containing market data and instrument conventions files) and requested currencies are given as command line arguments. Conventions object and market data (pandas data frame) are being created and fed to curve builder object in its constructor. Finally, curves are being requested for each currency.

It can be seen, that we can actually create piecewise yield term structures for any currency (as long as market data and conventions are available) with a very few lines of code by using this kind of construction scheme. In essence, all the complexity involved is still there, but we have effectively moved all "janitor work" into specific classes (builder, conversions) and files (conventions, market data).

Configuration for a new currency should be straightforward: add instruments into market data file (ticker-value-pairs). Then, add new section for this new currency to conventions file (including configuration sub-sections for all instruments in this new currency). Also, some minor additions might be needed in conversion class.

Program execution is shown below.


Thanks for reading my blog.
-Mike

Sunday, July 7, 2019

Python: creating QuantLib swap transactions using JSON deserialization

This time, I wanted to apply my JSON handler class for constructing QuantLib vanilla interest rate swap transaction instances from JSON files. The idea is to have several swap transaction JSON presentations in a directory, then create QuantLib instances of these transactions and finally request QuantLib to calculate PV for each transaction. My previous version of a similar scheme (only using XML files) can be found in here. I would say, that this new version is already much more straightforward to use. All required files in order to get this example program working, can be downloaded from my GitHub repository in here.

JsonHandler utility class for JSON serialization/deserialization is shown below. In a nutshell, this class has only two methods: FileToObject, which will re-hydrate JSON file content to a custom object (deserialization) and ObjectToFile, which will hydrate custom object into JSON file content (serialization). However, in this program we only need to deserialize (re-hydrate) transactions.

# class for handling transformations between custom object and JSON file
class JsonHandler:
    
    # transform json file to custom object
    def FileToObject(file):
        # nested function: transform dictionary to custom object
        def DictionaryToObject(dic):
            if("__class__" in dic):
                class_name = dic.pop("__class__")
                module_name = dic.pop("__module__")
                module = __import__(module_name)
                class_ = getattr(module, class_name)
                obj = class_(**dic)
            else:
                obj = dic
            return obj        
        return DictionaryToObject(json.load(open(file, 'r')))
    
    # transform custom object to json file
    def ObjectToFile(obj, file):
        # nested function: check whether an object can be json serialized
        def IsSerializable(obj):
            check = True
            try:
                # throws, if an object is not serializable
                json.dumps(obj)
            except:
                check = False
            return check
        # nested function: transform custom object to dictionary
        def ObjectToDictionary(obj):
            dic = { "__class__": obj.__class__.__name__, "__module__": obj.__module__ }            
            dic.update(obj.__dict__)
            # remove all non-serializable items from dictionary before serialization
            keysToBeRemoved = []
            for k, v in dic.items():
                if(IsSerializable(v) == False):
                    keysToBeRemoved.append(k)
            [dic.pop(k, None) for k in keysToBeRemoved]
            return dic
        json.dump(ObjectToDictionary(obj), open(file, 'w'))

Next, let us take a look at VanillaSwap class, which is actually wrapping QuantLib VanillaSwap class. Data members are initialized at constructor. It should be noted, that we will construct the actual QuantLib instrument instance in setPricingEngine method, after receiving correct pricing engine (DiscountingSwapEngine) and constructed index object (including required set of reference index fixings) for floating leg. Class method NPV will just delegate our valuation request for wrapped VanillaSwap instance.

# wrapper class for QuantLib vanilla interest rate swap
class VanillaSwap(object):
    
    def __init__(self, ID, swapType, nominal, startDate, maturityDate, fixedLegFrequency, 
        fixedLegCalendar, fixedLegConvention, fixedLegDateGenerationRule, fixedLegRate, fixedLegDayCount,
        fixedLegEndOfMonth, floatingLegFrequency, floatingLegCalendar, floatingLegConvention, 
        floatingLegDateGenerationRule, floatingLegSpread, floatingLegDayCount, floatingLegEndOfMonth):

        self.ID = ID
        self.swapType = swapType
        self.nominal = nominal
        self.startDate = startDate
        self.maturityDate = maturityDate
        self.fixedLegFrequency = fixedLegFrequency
        self.fixedLegCalendar = fixedLegCalendar
        self.fixedLegConvention = fixedLegConvention
        self.fixedLegDateGenerationRule = fixedLegDateGenerationRule
        self.fixedLegRate = fixedLegRate
        self.fixedLegDayCount = fixedLegDayCount
        self.fixedLegEndOfMonth = fixedLegEndOfMonth
        self.floatingLegFrequency = floatingLegFrequency
        self.floatingLegCalendar = floatingLegCalendar
        self.floatingLegConvention = floatingLegConvention
        self.floatingLegDateGenerationRule = floatingLegDateGenerationRule
        self.floatingLegSpread = floatingLegSpread
        self.floatingLegDayCount = floatingLegDayCount
        self.floatingLegEndOfMonth = floatingLegEndOfMonth
        
    def setPricingEngine(self, engine, floatingLegIborIndex):
        # create fixed leg schedule
        fixedLegSchedule = ql.Schedule(
            Convert.to_date(self.startDate), 
            Convert.to_date(self.maturityDate),
            ql.Period(Convert.to_frequency(self.fixedLegFrequency)), 
            Convert.to_calendar(self.fixedLegCalendar), 
            Convert.to_businessDayConvention(self.fixedLegConvention),
            Convert.to_businessDayConvention(self.fixedLegConvention),
            Convert.to_dateGenerationRule(self.fixedLegDateGenerationRule),
            self.fixedLegEndOfMonth)
        
        # create floating leg schedule
        floatingLegSchedule = ql.Schedule(
            Convert.to_date(self.startDate), 
            Convert.to_date(self.maturityDate),
            ql.Period(Convert.to_frequency(self.floatingLegFrequency)), 
            Convert.to_calendar(self.floatingLegCalendar), 
            Convert.to_businessDayConvention(self.floatingLegConvention),
            Convert.to_businessDayConvention(self.floatingLegConvention),
            Convert.to_dateGenerationRule(self.floatingLegDateGenerationRule),
            self.floatingLegEndOfMonth)

        # create vanilla interest rate swap instance
        self.instrument = ql.VanillaSwap(
            Convert.to_swapType(self.swapType), 
            self.nominal, 
            fixedLegSchedule, 
            self.fixedLegRate, 
            Convert.to_dayCounter(self.fixedLegDayCount), 
            floatingLegSchedule,
            floatingLegIborIndex, # use given index argument
            self.floatingLegSpread, 
            Convert.to_dayCounter(self.floatingLegDayCount))    
        
        # pair instrument with pricing engine
        self.instrument.setPricingEngine(engine)        

    def NPV(self):
        return self.instrument.NPV()

Let us then take a look at the actual JSON feed. One may notice quickly, that there is no QuantLib data types in this source file. The idea is, that in the first stage, VanillaSwap class instance will be created and all its data members will be "in-built Python data types", shown in this source file (string, float, boolean, etc.).

{
  "__class__": "VanillaSwap",
  "__module__": "__main__",
  "ID": "002",
  "swapType": "PAYER",
  "nominal": 48000000,
  "startDate": "2018-03-14",
  "maturityDate": "2028-03-14",
  "fixedLegFrequency": "ANNUAL",
  "fixedLegCalendar": "TARGET",
  "fixedLegConvention": "MODIFIEDFOLLOWING",
  "fixedLegDateGenerationRule": "BACKWARD",
  "fixedLegRate": 0.019,
  "fixedLegDayCount": "ACTUAL360",
  "fixedLegEndOfMonth": false,
  "floatingLegFrequency": "QUARTERLY",
  "floatingLegCalendar": "TARGET",
  "floatingLegConvention": "MODIFIEDFOLLOWING",
  "floatingLegDateGenerationRule": "BACKWARD",
  "floatingLegSpread": 0.0007,
  "floatingLegDayCount": "ACTUAL360",
  "floatingLegEndOfMonth": false
}

Now, as we execute setPricingEngine method (which then creates leg schedules and the actual QuantLib VanillaSwap instance), one may also see that we are using Convert utility class for transforming specific in-built data types into specific QuantLib types (Date, Calendar, DayCounter, etc.). This utility class is shown here below. Needless to say, it is pretty far from being complete as such, but good enough for making a point.

# utility class for different QuantLib type conversions 
class Convert():
    
    # convert date string ('yyyy-mm-dd') to QuantLib Date object
    def to_date(s):
        monthDictionary = {
            '01': ql.January, '02': ql.February, '03': ql.March,
            '04': ql.April, '05': ql.May, '06': ql.June,
            '07': ql.July, '08': ql.August, '09': ql.September,
            '10': ql.October, '11': ql.November, '12': ql.December
        }
        arr = re.findall(r"[\w']+", s)
        return ql.Date(int(arr[2]), monthDictionary[arr[1]], int(arr[0]))
    
    # convert string to QuantLib businessdayconvention enumerator
    def to_businessDayConvention(s):
        if (s.upper() == 'FOLLOWING'): return ql.Following
        if (s.upper() == 'MODIFIEDFOLLOWING'): return ql.ModifiedFollowing
        if (s.upper() == 'PRECEDING'): return ql.Preceding
        if (s.upper() == 'MODIFIEDPRECEDING'): return ql.ModifiedPreceding
        if (s.upper() == 'UNADJUSTED'): return ql.Unadjusted
        
    # convert string to QuantLib calendar object
    def to_calendar(s):
        if (s.upper() == 'TARGET'): return ql.TARGET()
        if (s.upper() == 'UNITEDSTATES'): return ql.UnitedStates()
        if (s.upper() == 'UNITEDKINGDOM'): return ql.UnitedKingdom()
        # TODO: add new calendar here
        
    # convert string to QuantLib swap type enumerator
    def to_swapType(s):
        if (s.upper() == 'PAYER'): return ql.VanillaSwap.Payer
        if (s.upper() == 'RECEIVER'): return ql.VanillaSwap.Receiver
        
    # convert string to QuantLib frequency enumerator
    def to_frequency(s):
        if (s.upper() == 'DAILY'): return ql.Daily
        if (s.upper() == 'WEEKLY'): return ql.Weekly
        if (s.upper() == 'MONTHLY'): return ql.Monthly
        if (s.upper() == 'QUARTERLY'): return ql.Quarterly
        if (s.upper() == 'SEMIANNUAL'): return ql.Semiannual
        if (s.upper() == 'ANNUAL'): return ql.Annual

    # convert string to QuantLib date generation rule enumerator
    def to_dateGenerationRule(s):
        if (s.upper() == 'BACKWARD'): return ql.DateGeneration.Backward
        if (s.upper() == 'FORWARD'): return ql.DateGeneration.Forward
        # TODO: add new date generation rule here

    # convert string to QuantLib day counter object
    def to_dayCounter(s):
        if (s.upper() == 'ACTUAL360'): return ql.Actual360()
        if (s.upper() == 'ACTUAL365FIXED'): return ql.Actual365Fixed()
        if (s.upper() == 'ACTUALACTUAL'): return ql.ActualActual()
        if (s.upper() == 'ACTUAL365NOLEAP'): return ql.Actual365NoLeap()
        if (s.upper() == 'BUSINESS252'): return ql.Business252()
        if (s.upper() == 'ONEDAYCOUNTER'): return ql.OneDayCounter()
        if (s.upper() == 'SIMPLEDAYCOUNTER'): return ql.SimpleDayCounter()
        if (s.upper() == 'THIRTY360'): return ql.Thirty360()

At this point, we have presented JSON handler class for performing required deserializations, VanillaSwap class for wrapping corresponding QuantLib class instance and Conversion utility class for performing required QuantLib type conversions. Finally, it is time to take a look how we can easily deserialize a batch of QuantLib VanillaSwap transaction JSON presentations from specific directory and request valuations for all instances.

# read all JSON files from repository, create vanilla swap instances
repository = sys.argv[1]
files = os.listdir(repository)
swaps = [JsonHandler.FileToObject(repository + file) for file in files]

# create valuation curve, index fixings and pricing engine
curveHandle = ql.YieldTermStructureHandle(ql.FlatForward(ql.Date(5, ql.July, 2019), 0.02, ql.Actual360()))
engine = ql.DiscountingSwapEngine(curveHandle)
index = ql.USDLibor(ql.Period(ql.Quarterly), curveHandle)
index.addFixings([ql.Date(12, ql.June, 2019)], [0.02])

# set pricing engine (and floating index) and request pv for all swaps
for swap in swaps:
    swap.setPricingEngine(engine, index)
    print(swap.ID, swap.NPV())

So, at this point the question might be "why bother"? In my opinion, by using deserialization scheme (such as the one presented in this post), we
  • have been avoiding significant amount of hard-coded stuff in our program. 
  • can set as many VanillaSwap JSON presentations into a directory as we want and then easily process these transactions without changing anything in our executing program. 
  • can relatively easily add implementations for new types of QuantLib instruments (add corresponding wrapper class, define constructor for capturing all required arguments, in setPricingEngine method assemble the actual QuantLib instrument instance and use Convert utility class for transforming in-built data types into QuantLib data types.

Program execution in terminal is shown below.


As always, thanks a lot for reading my blog.
-Mike


Friday, July 5, 2019

Python: JSON serialization/deserialization

Previous story continues. This post will present one possible implementation for JSON serialization/deserialization. Class JsonHandler (technically just a wrapper for json.load and json.dump methods) has only two methods: FileToObject will re-hydrate JSON file content to a custom object (deserialization) and ObjectToFile will hydrate custom object into JSON file content (serialization).

Class serialization using Python json package works fine with class data members, which are built-in Python data types (ex. integer, string, boolean, float, list, dictionary). However, custom data types such as class instance as data member are non-serializable. JsonHandler cannot handle such non-serializable data types either. As a safety net for facing such case, ObjectToFile method will automatically remove all non-serializable items from dictionary before serialization. For handling this type of serialization issues, I assume there are several more sophisticated third-party packages available.

Finally, it should be noted that when performing deserialization, JsonHandler transforms JSON string into dictionary, then transforms dictionary into object. Correspondingly, when performing serialization, it transforms object into dictionary, then transforms dictionary into JSON string. These operations (including nested methods) are adding some extra complexity into this otherwise simple and straightforward utility class.

Assume we would like to hydrate (serialize) Configurations class instance into JSON file. Note, that this class is actually containing non-serializable data type as its data member (class Whatever). This specific data member will be completely ignored in a process of serialization. However, as JSON file will be deserialized, instance of data member G will be created on class Configurations constructor, based on data members A and B (which are both serializable data types).

import json

# class for handling transformations between custom object and JSON file
class JsonHandler:
    
    # transform json file to custom object
    def FileToObject(file):
        # nested function: transform dictionary to custom object
        def DictionaryToObject(dic):
            if("__class__" in dic):
                class_name = dic.pop("__class__")
                module_name = dic.pop("__module__")
                module = __import__(module_name)
                class_ = getattr(module, class_name)
                obj = class_(**dic)
            else:
                obj = dic
            return obj        
        return DictionaryToObject(json.load(open(file, 'r')))
    
    # transform custom object to json file
    def ObjectToFile(obj, file):
        # nested function: check whether an object can be json serialized
        def IsSerializable(obj):
            check = True
            try:
                # throws, if an object is not serializable
                json.dumps(obj)
            except:
                check = False
            return check
        # nested function: transform custom object to dictionary
        def ObjectToDictionary(obj):
            dic = { "__class__": obj.__class__.__name__, "__module__": obj.__module__ }            
            dic.update(obj.__dict__)
            # remove all non-serializable items from dictionary before serialization
            keysToBeRemoved = []
            for k, v in dic.items():
                if(IsSerializable(v) == False):
                    keysToBeRemoved.append(k)
            [dic.pop(k, None) for k in keysToBeRemoved]
            return dic
        json.dump(ObjectToDictionary(obj), open(file, 'w'))

class Configurations(object):
    def __init__(self, A, B, C, D, E, F):
        # serializable data types
        self.A = A
        self.B = B
        self.C = C
        self.D = D
        self.E = E
        self.F = F
        # non-serializable data type
        self.G = Whatever(A, B)
        
class Whatever(object):
    def __init__(self, A, B):
        self.A = A
        self.B = B

# create class instance using 'primitive types'
new_config = Configurations(100, 3.14, True, [1, 2, 3], 'qwerty', { 'd1':1, 'd2':2 })

# print class members
print('printing data members of a newly created class instance:')
print(new_config.A)
print(new_config.B)
print(new_config.C)
print(new_config.D)
print(new_config.E)
print(new_config.F)
print(new_config.G.A)
print(new_config.G.B)
print()

# write object to json file
JsonHandler.ObjectToFile(new_config, '/home/mikejuniperhill/config.json')

# read object from json file
restored_config = JsonHandler.FileToObject('/home/mikejuniperhill/config.json')

print('printing data members of a restored class instance:')
print(restored_config.A)
print(restored_config.B)
print(restored_config.C)
print(restored_config.D)
print(restored_config.E)
print(restored_config.F)
print(restored_config.G.A)
print(restored_config.G.B)

Program execution in terminal is shown below.


Thanks for reading.
-Mike


Wednesday, July 3, 2019

Python: using JSON file for increasing program configurability

As the experience tells us, wrong decisions in program design and life will usually bite back hard. In order to avoid the most obvious traps leading into horrific maintenance problems, we should always design our programs to be free of any hard-coded parameters. By using configuration scheme presented in this post, flexible programs, which can use any desired set of input configurations, can be created. This means we can (as an example) execute a specific program (for valuing batch of transactions) several times, but using different set of configurations (different set of market data) for each execution. All example files can be downloaded from my GitHub page.

In this very simple example, Python program will just print a set of market and fixings data from CSV files, based on a given set of configurations. In order to keep this example program short and sweet, our JSON configuration file has only two configurations: directory addresses for market and fixings data CSV files, as follows.

{
  "MARKETDATA":"/home/mikejuniperhill/Market.csv",
  "FIXINGSDATA":"/home/mikejuniperhill/Fixings.csv"
}

Directory address of this configuration file will be given as a command line argument for the program. Based on this given configuration, program will then read configured data from files to be used in program. 


Example program is shown below. In the first stage, program will create configurations object. Technically, this object is just a wrapper for dictionary data structure. Any specific configuration can be accessed by using Python version of index operator overloading. After this, program reads data from configured CSV files into DataFrame objects and prints their contents to terminal.

import json
import sys
import pandas

# class for hosting configurations
class Configurations:
    inner = {}
    # read JSON configuration file to dictionary
    def __init__(self, filePathName):
        self.inner = json.load(open(filePathName))
        self.inner = {k.upper(): v for k, v in self.inner.items()}
    # return value for a given configuration key
    # 'overload' indexing operator
    def __getitem__(self, key):
        return self.inner[key.upper()]

# configuration file string is command line argument
configurationsFilePathName = sys.argv[1]

# create configurations object
config = Configurations(configurationsFilePathName)

# create market data based on configuration
market = pandas.read_csv(config['MarketData'])
print('EUR swap curve:')
print(market.head())

# create fixings data based on configuration
fixings = pandas.read_csv(config['FixingsData'])
print('6M Euribor fixings:')
print(fixings.head())

Handy tool for constructing and testing syntactic correctness of any JSON file can be found in here. Finally, thanks for reading.
-Mike

Wednesday, May 1, 2019

Python-SciPy: Optimizing Smooth Libor Forward Curve

In my previous post, I presented how to use Python SciPy Optimization package for solving zero-coupon rate term structure from a given set of zero-coupon bond prices numerically. In this post, the same approach will be used in order to solve smooth Libor forward curve from a given set of vanilla swaps. Example of applying this scheme using Solver and Excel/VBA can be found in here.

In order to value fixed income derivatives cash flows, relevant forward rates and discount factors have to be defined from bootstrapped zero-coupon curve. In a Libor world, we use cash and FRA contracts (or futures contracts) in a short-end of the curve, while in a long-end of the curve we use swap contracts. Let us assume for a moment, that we bootstrap USD 3M zero-coupon curve, in order to get 3M forward rates on a quarterly basis. While bootstrapping approach usually gives smooth curve within short-end of the curve, it will usually fail to do this within long-end of the curve. This happens, because there is no swap contracts available in a long-end of the curve and hereby, we need to do a lot of interpolations for required swap rates. The resulting forward curve then looks like a chain of waterfalls and for the long-end of the curve, smoothness will be lost. This topic has been thoroughly covered in chapter three within this excellent book by Richard Flavell.

In a nutshell, we first define the shortest end of the curve (using spot cash rate) and then we just guess the rest of the forward rates. After this, we minimize sum of squared differences between adjacent forward rates, subject to constraints. In this case, constraints are present values of swaps, which by definition will be zero. When this optimization task has been performed, the resulting forward curve will successfully re-price the current swap market.


Bloomberg forward curve screen for the same set of data is available in here. Finally, thanks again for reading my blog.
-Mike

import numpy as np
import scipy.optimize as opt
import matplotlib.pyplot as pl

# sum of squared errors of all decision variables
# args: 0 = array of given initial rates, 1 = scaling factor
def ObjectiveFunction(x, args):
    # concatenate given initial rates and given 'guesses' for forward rates
    x = np.concatenate([args[0], x])
    return np.sum(np.power(np.diff(x), 2) * args[1])

# x = array of Libor forward rates
# args: 0 = swap rate, 1 = years to maturity, 2 = floating leg payments per year, 
# 3 = notional, 4 = array of given initial rates
def VanillaSwapPV(x, args):
    # PV (fixed payer swap) = -swapRate * Q(T) + (1 - DF(T))
    # where Q(T) is sumproduct of fixed leg discount factors and corresponding time accrual factors
    # assumption : fixed leg is always paid annually
    # since fixed leg is paid annually and maturity is always integer, 
    # time accrual factor will always be exactly 1.0
    
    # concatenate given initial rates and given 'guesses' for forward rates
    x = np.concatenate([args[4], x])
    DF = 0.0
    Q  = 0.0
    floatingLegTenor = 1 / args[2]
    nextFixedLegCouponDate = 1
    currentTimePoint = 0.0
    nCashFlows = int(args[1] * args[2])
    
    for i in range(nCashFlows):
        currentTimePoint += floatingLegTenor
        # first rate is always spot rate: calculate first spot discount factor
        if (i == 0):
            DF = 1 / (1 + x[i] * floatingLegTenor)
        # other rates are always forward rates
        if (i > 0):
            # solve current spot discount factor using previous spot discount factor
            # and current forward discount factor: DF(0,T) = DF(0,t) * DF(t,T), where (0 < t < T)
            DF *= (1 / (1 + x[i] * floatingLegTenor))
            if ((currentTimePoint - nextFixedLegCouponDate) == 0):
                Q += DF
                nextFixedLegCouponDate += 1
                
    return (-args[0] * Q + (1.0 - DF)) * args[3]

# array of given initial rates (the first given rate has to be spot cash rate)
# here, we give only one: 3M spot Libor fixing rate ('cash-to-first-future')
initialRates = np.array([0.006276])
scalingFactor = 1000000.0

# vanilla swap pricing functions as constraints
# args: swapRate, yearsToMaturity, floatingLegPaymentFrequency, notional, array of given initial rates
swaps = ({'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.0078775, 1, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.009295, 2, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.0103975, 3, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.01136, 4, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.012268, 5, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.013183, 6, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.01404, 7, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.014829, 8, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.01554, 9, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.016197, 10, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.016815, 11, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.017367, 12, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.018645, 15, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.01996, 20, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.020615, 25, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.02097, 30, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.021155, 40, 4, scalingFactor, initialRates]]},
        {'type': 'eq', 'fun': VanillaSwapPV, 'args': [[0.021017, 50, 4, scalingFactor, initialRates]]})

# initial guesses for Libor forward rates up to 50 years
# number of rates: 50 * 4 - 1 (years to maturity * floating leg payments per year - first given cash spot rate)
initialGuesses = np.full(199, 0.006)
model = opt.minimize(ObjectiveFunction, initialGuesses, args = ([initialRates, scalingFactor]), method = 'SLSQP', options = {'maxiter': 500}, constraints = swaps)

# print selected model results
print('Success: ' + str(model.success))
print('Message: ' + str(model.message))
print('Number of iterations: ' + str(model.nit))
print('Objective function (sum of squared errors): ' + str(model.fun))
#print('Changing variables (Libor forward rates): ' + str(model.x * 100))
pl.plot(model.x)
pl.show()

Tuesday, April 30, 2019

Python-SciPy: Solving Zero-Coupon Term Structure Using Optimization

This post is presenting how to use Python SciPy Optimization package for solving out zero-coupon rate term structure from a given set of zero-coupon bond prices. Needless to say, we do not need any numerical method to do this, since we have exact analytical formulas for backing out zero-coupon rates from zero-coupon bond prices. However, approach presented in this relatively simple example can be applied into more interesting schemes, such as solving out smooth Libor forward curve from a given set of vanilla swaps. Example of such scheme using Solver and Excel/VBA can be found in here.

Let us assume zero-coupon rate term structure as shown below. Let us also assume, that the only information we can observe is the zero-coupon bond prices. Our task is to solve zero-coupon rates term structure.


In a nutshell, we first set initial guesses for ten zero-coupon rates. After this we minimize sum of squared differences between adjacent zero-coupon rates (in objective function), but subject to constraints. In this case, constraints are differences between observed zero-coupon bond market prices and calculated bond prices, which need to be pushed to zero. When this optimization task has been completed, the resulting zero-coupon term structure will successfully re-price the current zero-coupon bond market, while curve smoothness is maximized. Example program results are shown below.


Thanks for reading this blog.
-Mike

import numpy as np
import scipy.optimize as opt
import matplotlib.pyplot as pl

# sum of squared errors of decision variables
def ObjectiveFunction(x, args):
    return np.sum(np.power(np.diff(x), 2) * args[0])

# zero coupon bond pricing function
def ZeroCouponBond(x, args):
    # return difference between calculated and market price
    return ((1 / (1 + x[args[3]])**args[2]) - args[0]) * args[1]

# zero coupon bond pricing functions as constraints
# args: market price, scaling factor, maturity, index number for rate array
zeroPrices = ({'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.998801438274071, 1000000.0, 1.0, 0]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.996210802629012, 1000000.0, 2.0, 1]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.991943543964159, 1000000.0, 3.0, 2]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.981028206597786, 1000000.0, 4.0, 3]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.962851266220459, 1000000.0, 5.0, 4]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.946534719794057, 1000000.0, 6.0, 5]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.924997530805076, 1000000.0, 7.0, 6]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.912584111300984, 1000000.0, 8.0, 7]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.892632531026722, 1000000.0, 9.0, 8]]},
            {'type': 'eq', 'fun': ZeroCouponBond, 'args': [[0.877098137542374, 1000000.0, 10.0, 9]]})

# initial guesses for ten zero-coupon rates
initialGuess = np.full(10, 0.005)
model = opt.minimize(ObjectiveFunction, initialGuess, args = ([1000000.0]), method = 'SLSQP', constraints = zeroPrices)

# print selected model results
print('Success: ' + str(model.success))
print('Message: ' + str(model.message))
print('Number of iterations: ' + str(model.nit))
print('Objective function (sum of squared errors): ' + str(model.fun))
print('Changing variables (zero-coupon rates): ' + str(model.x * 100))
pl.plot(model.x)
pl.show()

Friday, April 26, 2019

Python: Path Generator for Correlated Processes

One reader was interested to know, how to simulate correlated asset paths by using just Python libraries, without using QuantLib. This blog post is presenting the result of woodshedding this stuff. A couple of notes:
  • GeneratePaths method can be used to simulate paths for a single process or multiple processes, based on a given (or non-existing) correlation matrix.
  • Method returns Numpy array having dimensions based on the given number of processes, number of paths and number of time steps.
  • Discretized stochastic processes for generator method to be simulated are defined as lambda methods. This approach makes it relatively easy to implement (almost) any desired single-factor model.
The program is enough commented and should be self-explainable. Thanks for reading this blog.
-Mike

import numpy as np
import matplotlib.pyplot as pl

# returns ndarray with the following dimensions: nProcesses, nPaths, nSteps
def GeneratePaths(spot, process, maturity, nSteps, nPaths, correlation = None):
    dt = maturity / nSteps
    
    # case: given correlation matrix, create paths for multiple correlated processes
    if (isinstance(correlation, np.ndarray)):
        nProcesses = process.shape[0]
        result = np.zeros(shape = (nProcesses, nPaths, nSteps))
        
        # loop through number of paths
        for i in range(nPaths):
            # create one set of correlated random variates for n processes
            choleskyMatrix = np.linalg.cholesky(correlation)
            e = np.random.normal(size = (nProcesses, nSteps))            
            paths = np.dot(choleskyMatrix, e)
            # loop through number of steps
            for j in range(nSteps):
                # loop through number of processes
                for k in range(nProcesses):
                    # first path value is always current spot price
                    if(j == 0):
                        result[k, i, j] = paths[k, j] = spot[k]
                    else:
                        # use SDE lambdas (inputs: previous spot, dt, current random variate)
                        result[k, i, j] = paths[k, j] = process[k](paths[k, j - 1], dt, paths[k, j])

    # case: no given correlation matrix, create paths for a single process
    else:
        result = np.zeros(shape = (1, nPaths, nSteps))
        # loop through number of paths
        for i in range(nPaths):
            # create one set of random variates for one process
            path = np.random.normal(size = nSteps)
            # first path value is always current spot price
            result[0, i, 0] = path[0] = spot
            # loop through number of steps
            for j in range(nSteps):
                if(j > 0):
                    # use SDE lambda (inputs: previous spot, dt, current random variate)
                    result[0, i, j] = path[j] = process(path[j - 1], dt, path[j])
    return result

# Geometric Brownian Motion parameters
r = 0.03
v = 0.25

# define lambda for process (inputs: spot, dt, random variate)
BrownianMotion = lambda s, dt, e: s + r * s * dt + v * s * np.sqrt(dt) * e   

# general simulation-related parameters
maturity = 1.0
nPaths = 10
nSteps = 250

# case: one process
SingleAssetPaths = GeneratePaths(100.0, BrownianMotion, maturity, nSteps, nPaths)
for i in range(nPaths):
    pl.plot(SingleAssetPaths[0, i, :])
pl.show()

# case: two correlated processes
matrix = np.array([[1.0, 0.999999], [0.999999, 1.0]])
spots = np.array([100.0, 100.0])
processes = np.array([BrownianMotion, BrownianMotion])
MultiAssetPaths = GeneratePaths(spots, processes, maturity, nSteps, nPaths, matrix)
f, subPlots = pl.subplots(processes.shape[0], sharex = True)
for i in range(processes.shape[0]): 
    for j in range(nPaths):
        subPlots[i].plot(MultiAssetPaths[i, j, :])
pl.show()

Monday, February 18, 2019

C#/Python: Creating Python Wrapper for C# Class by Using Python for .NET

Interoperability is just amazing concept. Sometimes, instead re-inventing the wheel again for a new language, it might be easier to recycle the old stuff. Creating Python wrapper for C++ program was presented in previous post. This post will present simple steps for creating Python wrapper for a simple C#.NET class.

Python for .NET

Python for .NET is a package, that gives Python programmers nearly seamless integration with .NET Common Language Runtime. With this package, you can script .NET applications or build entire applications in Python, using .NET services and components written in any language that targets the CLR (C#, VB.NET, F#, C++/CLI). Download package from here.

Create C# class

In Visual Studio, create a new C# class library project under the namespace CsLibrary. Create C# class Functions into this class project. The content of this class is presented below.

using System;

namespace CsLibrary
{
    // C# class
    public class Functions
    {

        public double Add(double a, double b) {
            return a + b;
        }

        public double Subtract(double a, double b) {
            return a - b;
        }

        public double Multiply(double a, double b) {
            return a * b;
        }

        public double Divide(double a, double b) {
            return a / b;
        }

    }
}

Create wrapper for C# class

In order to access this class from Python, we need to have wrapper class, which inherits from DynamicObject. Add the following new class to existing solution. Effectively, this class is just object adapter, which delegates function calls to our previous C# class.

using System;
using System.Dynamic;

namespace CsLibrary {

    public class PyWrapper : DynamicObject {

        // wrapped C# class
        private Functions functions;

        // ctor
        public PyWrapper() {
            functions = new Functions();
        }        
        
        public double Add(double a, double b) {
            return functions.Add(a, b);
        }

        public double Subtract(double a, double b) {
            return functions.Subtract(a, b);
        }

        public double Multiply(double a, double b) {
            return functions.Multiply(a, b);
        }

        public double Divide(double a, double b) {
            return functions.Divide(a, b);
        }
    }
}

Use wrapper class in Python

The following example program is using C# class wrapper (CsLibrary.dll) in Python.

import clr
clr.AddReference(r'..\CsLibrary\bin\Release\CsLibrary.dll')
from CsLibrary import PyWrapper
wrapper = PyWrapper()

x = 1.23
y = 2.34

print(wrapper.Add(x, y))
print(wrapper.Subtract(x, y))
print(wrapper.Multiply(x, y))
print(wrapper.Divide(x, y))

# 3.57
# -1.1099999999999999
# 2.8781999999999996
# 0.5256410256410257

That's it. The files can be downloaded from my GitHub page. Thanks for reading my blog.
-Mike

Sunday, February 10, 2019

C++/Python: Creating Python Wrapper for C++ Class by Using SWIG

If the need sometimes arises, existing C++ libraries can be interfaced relatively easy to be used in Python by using SWIG wrapper. SWIG stands for Simplified Wrapper and Interface Generator and it is an open-source software tool used to connect computer programs or libraries written in C or C++ with scripting languages, such as Python. As one extremely motivating example, QuantLib C++ libraries have been made available for Python by using SWIG wrappers. Complete documentation for SWIG 3.0 can be found in here. The actual SWIG package can be downloaded in here. By taking a look at the documentation, one may understand quickly, that in this post only the tip of the iceberg will get scratched.

Also, it should be noted at this point, that this post is assuming all operations taking place in Linux environment. Corresponding instructions for Windows users can be found in SWIG documentation. This blog post is presenting, how to interface custom C++ random generator class to be used in Python. The original (template) class implementation can be found in here.

Header and implementation files for simple C++ random number generator class are presented below.

Header file (RG.h)

#include <algorithm>
#include <functional>
#include <random>

class Generator {
public:
 Generator(unsigned long seed);
 void operator()(std::vector<double>& v);
private:
 std::function<double(double)> randomGenerator;
 std::normal_distribution<double> distribution;
 std::mt19937 uniformGenerator;
};

Implementation file (RG.cpp)

#include "RG.h"

Generator::Generator(unsigned long seed) {
  // construct lambda method for processing standard normal random number
  randomGenerator = [this](double x)-> double {
   x = distribution(uniformGenerator);
   return x;
  };
  uniformGenerator.seed(seed);
}

// fill client-given vector with random variates from standard normal distribtuion
void Generator::operator()(std::vector<double>& v) {
  std::transform(v.begin(), v.end(), v.begin(), randomGenerator);
}

The class functionality is simple and straightforward. First, create a class implementation by giving desired seed value in constructor. In constructor, C++ function object will be created. This function object will ultimately create our normally distributed random variates. Client will request a new set of random variates by giving a reference for STL vector by using parenthesis operator, which has been overloaded here for syntactic reasons only.

SWIG interface file (RG.i)

A simple SWIG interface for our class can be built by simply wrapping the header file as follows.

%module RG
%{
#include "RG.h"
%}

%include "std_vector.i"
%template(DoubleVector) std::vector<double>;

%include "RG.h"

Python does not know anything about std::vector. The std_vector.i library provides support for C++ STL vector class. Then, all we need to do is to instantiate different versions of vector for all the specific types we would like to use in Python. For our example class, we want to use vector consisting of double data types. Using this library involves the use of the %template directive. In Python code, C++ vector will be used by using alias DoubleVector.

SWIG build

All in all we have now three files in our folder: RG.h, RG.cpp and RG.i. With terminal opened in the folder consisting the previous three files, the following three commands will create Python wrapper for our C++ class.

$ swig -c++ -python RG.i
$ g++ -fpic -c -I/home/mikejuniperhill/anaconda3/include/python3.7m RG.cpp RG_wrap.cxx
$ g++ -shared RG.o RG_wrap.o -o _RG.so

In the second command, a correct parameter for -I argument can be found by using the following command in terminal.

$ python3-config --cflags

After these three steps, our C++ program can be accessed and used in Python program. The following simple example program is requesting a vector of standard normal random numbers from our wrapped C++ class and uses those for calculating Monte Carlo PV for one European call option.

# import RG module
import SwigTester.RG as RG
import numpy as np

# set seed, create generator object
seed = 0
generator = RG.Generator(seed)

# set vector size, initialize vector
steps = 1000
vector = RG.DoubleVector(steps)

# request generator to fill vector with standard normal variates 
generator(vector)
# copy content to numpy array
e = np.array(vector)

# use variates to value one european call option
# set parameters
s0 = 100.0
x = 100.0
t = 1.25
v = 0.25
r = 0.01

# use vectorization in numpy, pre-calculate components
drift = (r - 0.5 * v * v) * t
diffusion = v * np.sqrt(t)
df = np.exp(-r * t)

# get option value as discounted average of all terminal payoffs
c0 = np.mean(np.maximum(s0 * np.exp(drift + diffusion * e) - x, 0.0)) * df
print(c0)

Note, that I imported SwigTester.RG, because I created Python wrapper module directly into this specific folder.

As a SWIG newcomer, one may expect to face all kinds of cryptic installation and other infuriating compatibility issues. As always, Google is the best friend along this cruel and unusual phase. But, have faith - and you'll be rewarded with all wonders and joys of SWIG wrapper.

All relevant files can be found directly from my GitHub repository. Thanks for reading my blog.
-Mike